
AP Statistics 1.11 Random Sampling- Exam Style Questions - FRQs - New Syllabus
Question
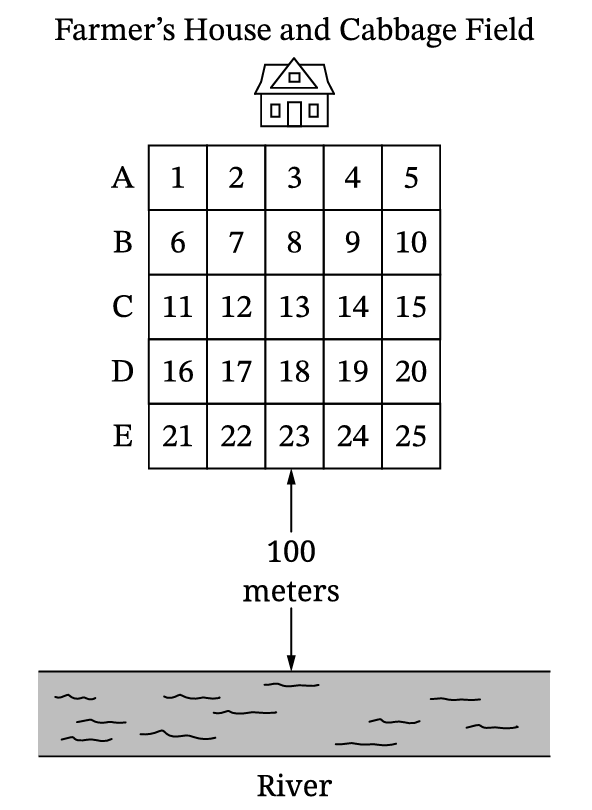
- Sampling method I: Select region 3, which is closest to the farmer’s house and farthest from the river. Examine every cabbage plant in the region for aphid damage.
- Sampling method II: Randomly select one row (A, B, C, D, or E). For every region in the selected row, examine every cabbage plant for aphid damage.
- Sampling method III: Randomly select one region from each of rows A, B, C, D, and E. For each selected region, examine every cabbage plant for aphid damage.
Most-appropriate topic codes (AP Statistics):
• Topic \(1.12\) — Potential Problems with Sampling (Parts \( \mathrm{A} \), \( \mathrm{B} \))
▶️ Answer/Explanation
A.
• Sampling method I is not an appropriate sampling method because it uses a convenience sample that lacks randomization.
• Since region 3 is located farthest from the river where aphid damage is believed to be lowest, this region is not representative of the whole field and will likely lead to an underestimate of the true population proportion.
B.
• The selection of row E is likely to provide an overestimate of the true proportion of damaged cabbage plants.
• Row E is the row positioned closest to the river, meaning every single plant checked in this sample belongs to the high-risk zone where the farmer expects aphid damage to be at its peak concentration.
C.
• Label the 5 individual regions within row A with unique identifiers from 1 to 5.
• Use a random number generator or draw numbered slips from a hat to select one single region from row A.
• Repeat this exact independent drawing process for row B (regions 6 to 10), row C (regions 11 to 15), row D (regions 16 to 20), and row E (regions 21 to 25) to complete a stratified sample containing exactly 5 distinct regions.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(1.12\) — Potential Problems with Sampling (Part \( \mathrm{a} \))
▶️ Answer/Explanation
(a)
Keeping a daily journal introduces response bias because subjects are self-reporting. They might forget to log short walks or underestimate their distances, which would cause our sample’s average daily miles to be systematically biased too low compared to what they actually walked.
(b)
A representative sample is essential because it allows us to generalize our findings. By selecting randomly, our \(100\) adults look like the larger target population, meaning any inference we make about the relationship between walking and cholesterol isn’t skewed by an unrepresentative group.
(c)
No, we can’t claim causation here because this is an observational study, not an experiment. We didn’t randomly assign subjects to walk specific distances. Because of this lack of assignment, there could be confounding variables at play—like a person’s diet or general health consciousness—that simultaneously affect both how much they walk and their cholesterol levels.
Question
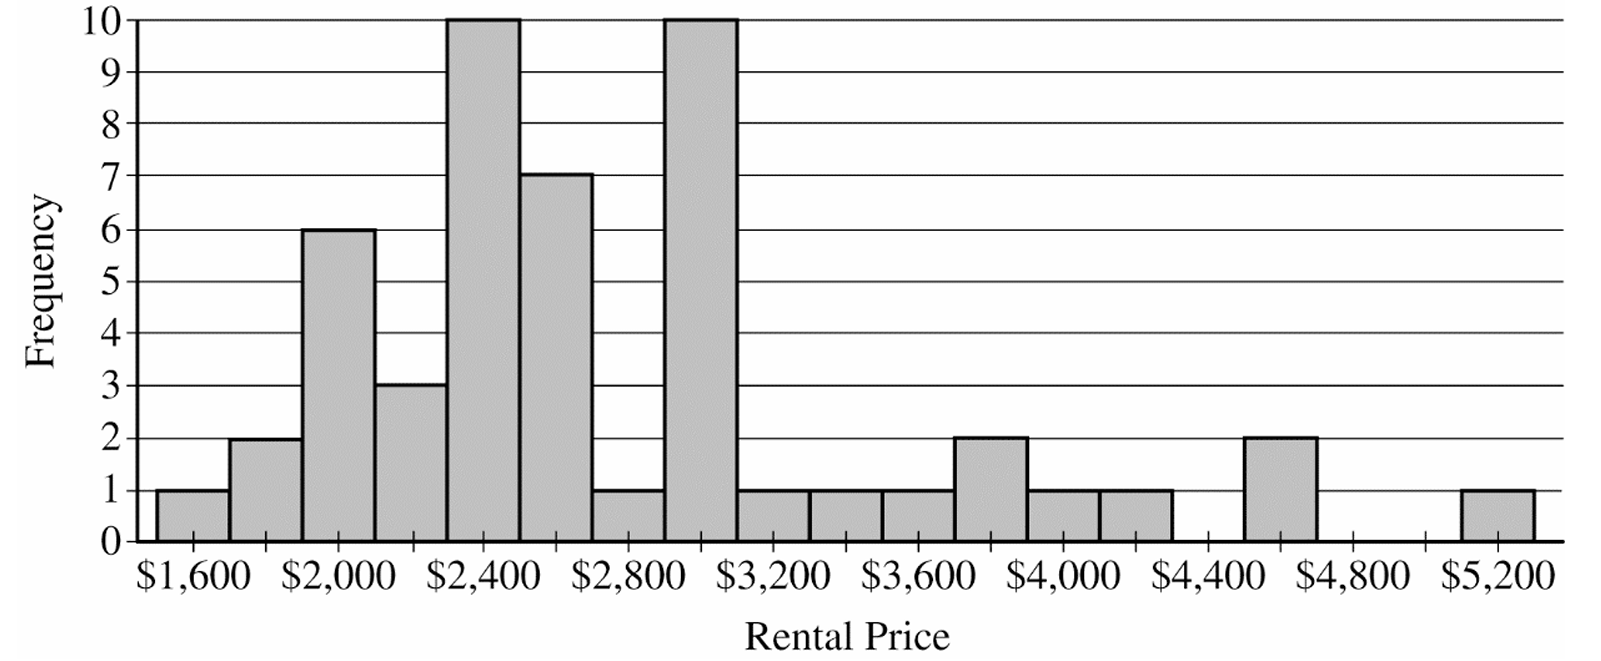
• Calculate and record the median of the sample.
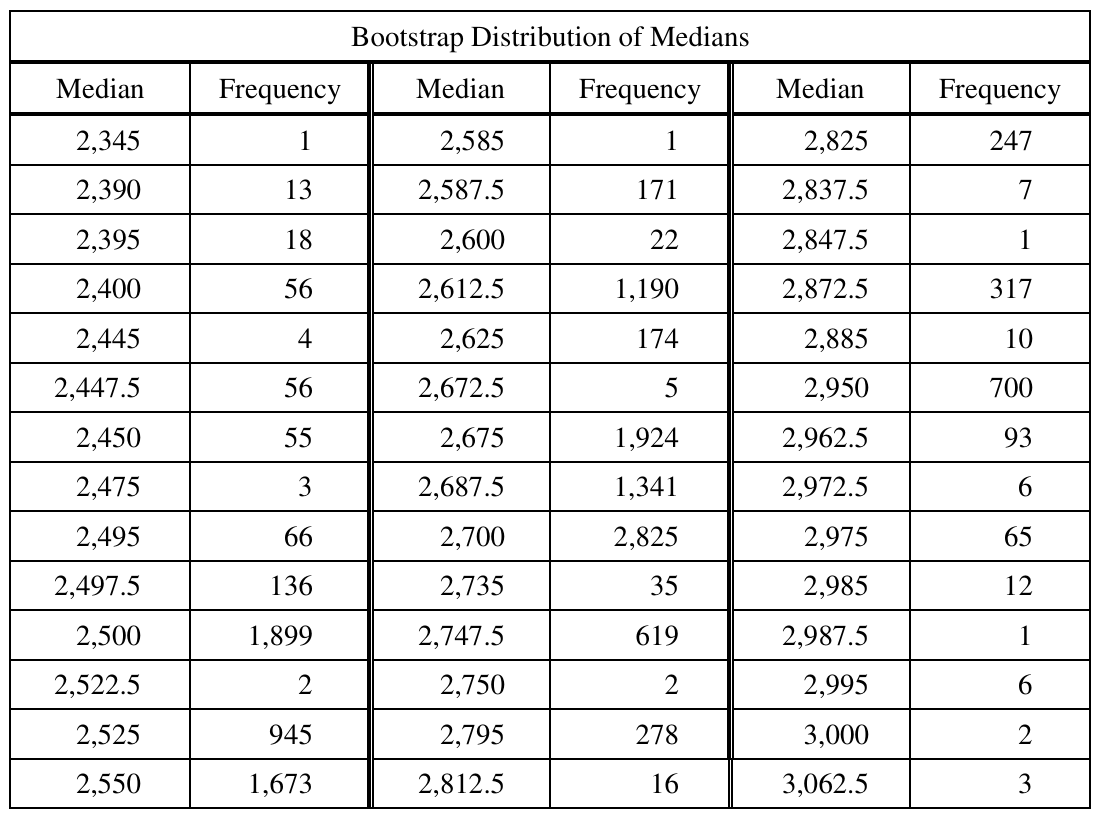
• Repeat the process to obtain a total of \(15,000\) medians.
Most-appropriate topic codes (AP Statistics):
• Topic \(1.12\) — Potential Problems with Sampling (Part \( \mathrm{a} \))
• Topic \(1.7\) — Summary Statistics for One Quantitative Variable (Parts \( \mathrm{b} \), \( \mathrm{d} \), \( \mathrm{e} \))
• Topic \(2.12\) — Central Limit Theorem and Sampling Distributions for Sample Means (Parts \( \mathrm{c} \), \( \mathrm{f} \))
▶️ Answer/Explanation
(a)
Because a random sample was used, it is appropriate to generalize the results to the population of all rental prices for one-bedroom apartments in the city that are listed on this particular website at the time the sample was taken.
(b)
The histogram indicates that the distribution of rental prices is strongly skewed to the right.
Because of this right skewness, the sample mean will be pulled substantially higher by a few very large rental prices.
Consequently, the sample mean would overestimate the typical rental price, whereas the sample median provides a more accurate representation of the center.
(c)
To develop a theoretical sampling distribution, Emma would need to obtain every possible sample of size \(50\) from the population of apartments listed on the website.
She would then compute the median rental price for each of these possible samples.
The entire collection of all these computed sample medians forms the theoretical sampling distribution for the sample median.
(d)
i. The \(5\text{th}\) percentile corresponds to the \((0.05)(15,000) = 750\text{th}\) value in the ordered data.
By keeping a running cumulative total of the frequencies down the columns, the \(750\text{th}\) value first falls in the row for the median of \(\$2,500\).
ii. The \(95\text{th}\) percentile corresponds to the \((0.95)(15,000) = 14,250\text{th}\) value in the ordered data.
Continuing to add the frequencies, the \(14,250\text{th}\) value falls in the row for the median of \(\$2,950\).
(e)
We need to sum the frequencies of all bootstrap medians from \(\$2,500\) to \(\$2,950\) inclusive.
\(\text{Sum} = 1,899 + 2 + \dots + 10 + 700 = 14,404\)
\(\text{Percentage} = \left(\dfrac{14,404}{15,000}\right) \times 100\% \approx 96.03\%\)
(f)
Based on our previous parts, an approximate \(96\%\) confidence interval for the median is \((\$2,500, \$2,950)\).
Interpretation: We are approximately \(96\%\) confident that the true median rental price of all one-bedroom apartments listed on this website for this city is between \(\$2,500\) and \(\$2,950\).
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(1.11\) — Random Smapling (Part \( \mathrm{b} \))
• Topic \(1.12\) — Potential Problems with Sampling (Part \( \mathrm{c} \))
▶️ Answer/Explanation
(a)
Explanatory variable: The person’s degree of cigarette smoking — specifically, whether or not the individual smoked at least two packs of cigarettes per day (smoker of at least two packs per day versus non-smoker at that level).
Response variable: Whether or not the person developed Alzheimer’s disease during the course of the 23-year study.
(b)
This is an observational study, not an experiment. In an experiment, researchers would have to actively assign the treatment — in this case, the level of cigarette smoking — to the participants. Instead, the researchers simply tracked the existing medical histories of 21,123 men and women over 23 years. The smoking status of each person was passively observed and recorded, not controlled or manipulated by the researchers. Since no treatment was imposed, this is an observational study.
(c)
A confounding variable is one that is related to the explanatory variable and also independently influences the response variable, making it difficult to determine whether the explanatory variable alone is responsible for the observed association.
Exercise status could be a confounding variable here for two reasons working together:
First, people who exercise regularly tend to be more health-conscious overall, and as a result are less likely to smoke heavily. So exercise status is related to the explanatory variable — smoking status. Heavy smokers are, on average, less likely to exercise regularly than non-smokers.
Second, regular exercise may independently reduce the risk of developing Alzheimer’s disease. So exercise status is also related to the response variable — development of Alzheimer’s disease.
Because of both of these relationships, the observed association between heavy smoking and higher rates of Alzheimer’s could be at least partly explained by the fact that heavy smokers tend to exercise less — and it is the lack of exercise, not the smoking itself, that contributes to the increased risk. This makes it impossible to determine from this study alone whether the association between smoking and Alzheimer’s reflects a true causal relationship or is merely the result of exercise status being linked to both.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(4.1\) — Sampling Distributions for Sample Means (Parts \( \mathrm{d} \), \( \mathrm{e} \), \( \mathrm{f} \))
▶️ Answer/Explanation
(a)
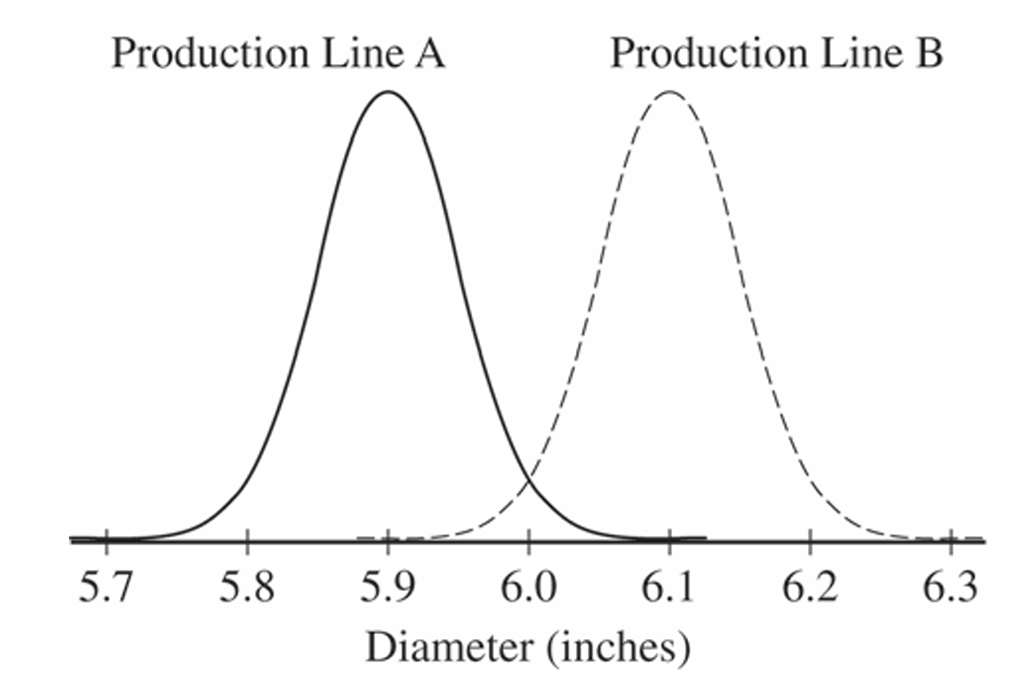
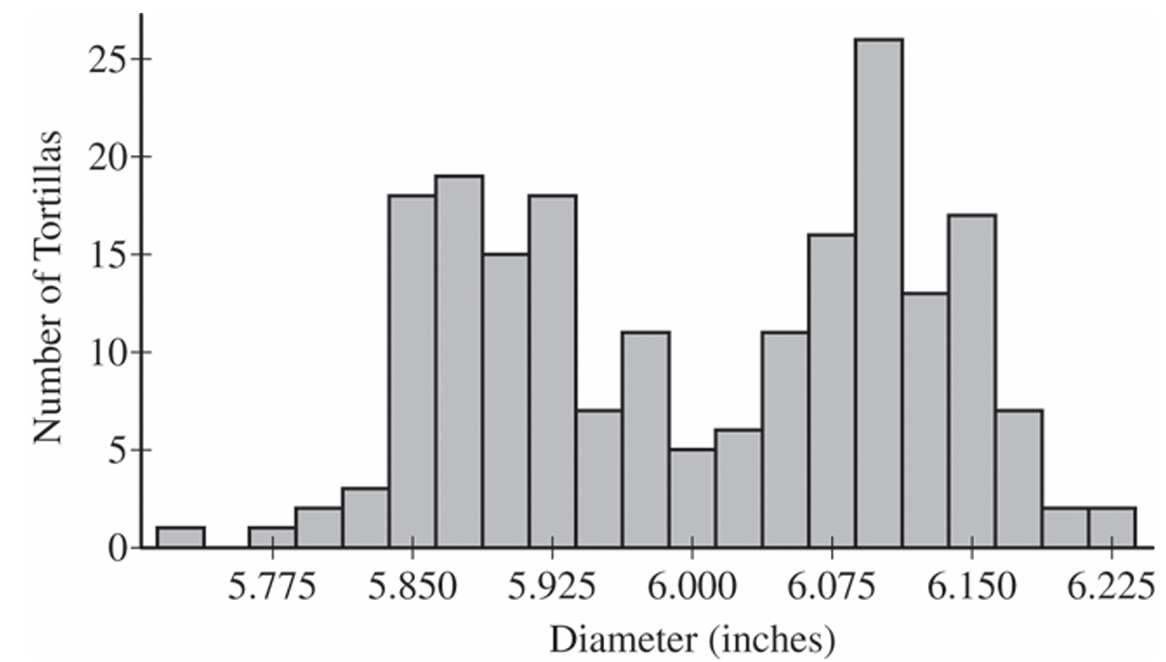
No, a sample obtained using Method 2 will not be representative of all tortillas made that day. The sample obtained using Method 2 will only represent the tortillas from one production line, not from the entire population. Because the distributions of diameters for the two production lines are different, sampling from only one line misses the true characteristics of the combined production.
(b)
Method 1 was most likely used to select this sample. The bimodal shape in the histogram of sample data indicates that tortillas were selected from both production lines (with peaks around \(5.9\) and \(6.1\)), which is what would happen using Method 1. Method 2 would be likely to produce a unimodal distribution centered at either \(5.9\) inches or \(6.1\) inches.
(c)
Method 2 would result in less variability in the sample of \(200\) tortillas on a given day because the sample comes from only one production line. Since the distributions of diameters are not the same for the two production lines, selecting tortillas from both lines (as in Method 1) combines their differences and results in more variable sample data.
(d)
The sampling distribution of the sample mean diameter for samples obtained using Method 1 would be approximately normal because the sample size is large (\(n = 200 \ge 30\)), satisfying the Central Limit Theorem.
The mean of the sampling distribution is:
\( \mu_{\bar{x}} = \mu = 6 \text{ inches} \)
The standard deviation (standard error) of the sampling distribution is:
\( \sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}} = \dfrac{0.11}{\sqrt{200}} \approx 0.0078 \text{ inch} \)
(e)
Method 1 would result in less variability in the distribution of the \(365\) sample means. The sample means from Method 1 will all be clustered very closely around the true population mean of \(6\) inches. Conversely, the sample means from Method 2 will be clustered around \(5.9\) inches on some days and around \(6.1\) inches on other days, creating a much wider overall spread for the \(365\) daily means.
(f)
Method 1 is more likely to produce a sample mean close to \(6\) inches. Even though both methods are unbiased estimators in the long run, Method 1 consistently samples from the entire population and its sample mean has very little variability (\(SE \approx 0.0078\)). On the day of the inspection, Method 2 will likely produce a sample mean clustered near either \(5.9\) inches or \(6.1\) inches, which is relatively far from the advertised \(6\) inches.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(1.11\) — Random Sampling (Part \( \mathrm{b} \))
• Topic \(1.11\) — Random Sampling (Part \( \mathrm{c} \) — stratified random sampling)
▶️ Answer/Explanation
(a)
The first \(500\) students who enter the football stadium are not likely to be representative of all \(70{,}000\) students at the university. Students who attend football games tend to have stronger school pride and a more positive connection to the university overall, which likely makes them more satisfied with the appearance of the buildings and grounds than the general student population. This means the sample would systematically overestimate the proportion of students who are satisfied — producing a positively biased estimate.
(b)
Step 1: Obtain a complete list of all \(70{,}000\) students at the university and assign each student a unique identification number from \(1\) to \(70{,}000\).
Step 2: Use a computer random number generator to generate \(500\) distinct random integers between \(1\) and \(70{,}000\), ignoring any repeated numbers that appear.
Step 3: Select the students whose assigned ID numbers match the \(500\) randomly generated numbers — these students form the simple random sample.
(c)
Stratification by campus would provide a more precise estimate than stratification by gender when the variability in students’ opinions about the appearance of the university buildings and grounds is greater between the two campuses than between the two genders. In other words, if the two campuses differ noticeably from each other in appearance (for example, one campus is newer or more attractive than the other), then students on different campuses will tend to have systematically different satisfaction levels — making campus a more effective stratification variable than gender.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 4.1 — Sampling Distributions for Sample Means (Parts b, c)
• Topic 4.1 — Sampling Distributions for Sample Means (Part d)
• Topic 1.11 — Random Sampling (Part d)
▶️ Answer/Explanation
(a)
To select a proper simple random sample, Peter could number all the students on the roster from 1 to 2,000.
Then, he can use a random number generator to produce numbers between 1 and 2,000.
He would ignore any repeated numbers and continue generating until he has a list of 100 unique random numbers.
The 100 students corresponding to those selected numbers will make up his sample.
(b)
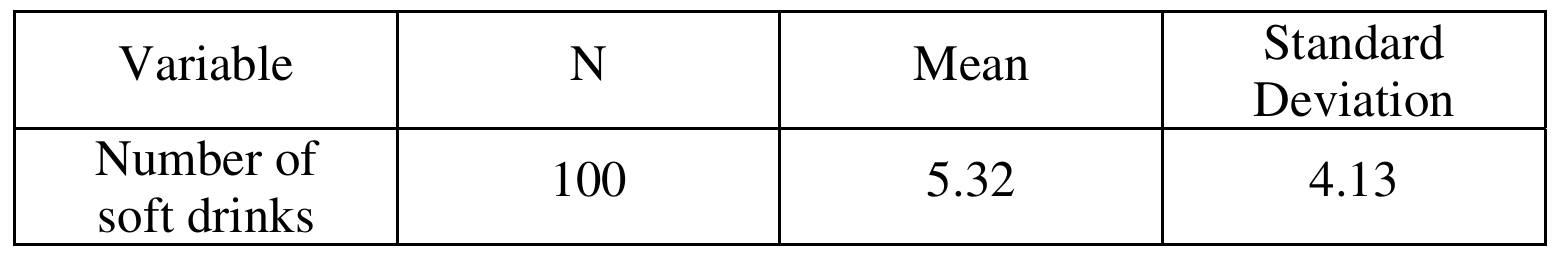
The estimated standard deviation of the sampling distribution of the sample mean (standard error) for Peter’s simple random sample is calculated using the formula \(\text{SE}(\bar{X}) = \frac{s}{\sqrt{n}}\).
Substituting the values from Peter’s sample: \(\text{SE}(\bar{X}) = \frac{4.13}{\sqrt{100}}\).
\(\text{SE}(\bar{X}) = \frac{4.13}{10} = 0.413\).
The estimated standard deviation of Peter’s point estimator is \(0.413\).
(c)
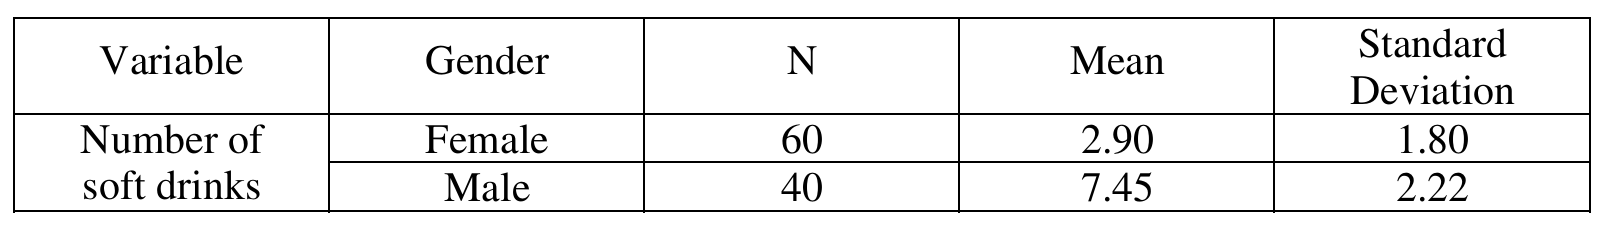
Rania’s point estimator is given by \(\bar{X}_{strat} = 0.6\bar{X}_{female} + 0.4\bar{X}_{male}\).
Because the two samples (female and male) are independent, the variance of the stratified estimator is the sum of the variances of each part, scaled by their squared weights:
\(\text{Var}(\bar{X}_{strat}) = (0.6)^2 \text{Var}(\bar{X}_{female}) + (0.4)^2 \text{Var}(\bar{X}_{male})\).
The variance for the female sample mean is \(\frac{s_{f}^2}{n_f} = \frac{(1.80)^2}{60} = \frac{3.24}{60} = 0.054\).
The variance for the male sample mean is \(\frac{s_{m}^2}{n_m} = \frac{(2.22)^2}{40} = \frac{4.9284}{40} = 0.12321\).
Substitute these into the combined variance equation:
\(\text{Var}(\bar{X}_{strat}) = (0.36)(0.054) + (0.16)(0.12321) = 0.01944 + 0.0197136 = 0.0391536\).
The estimated standard deviation is the square root of the variance:
\(\text{SE}(\bar{X}_{strat}) = \sqrt{0.0391536} \approx 0.198\).
(d)
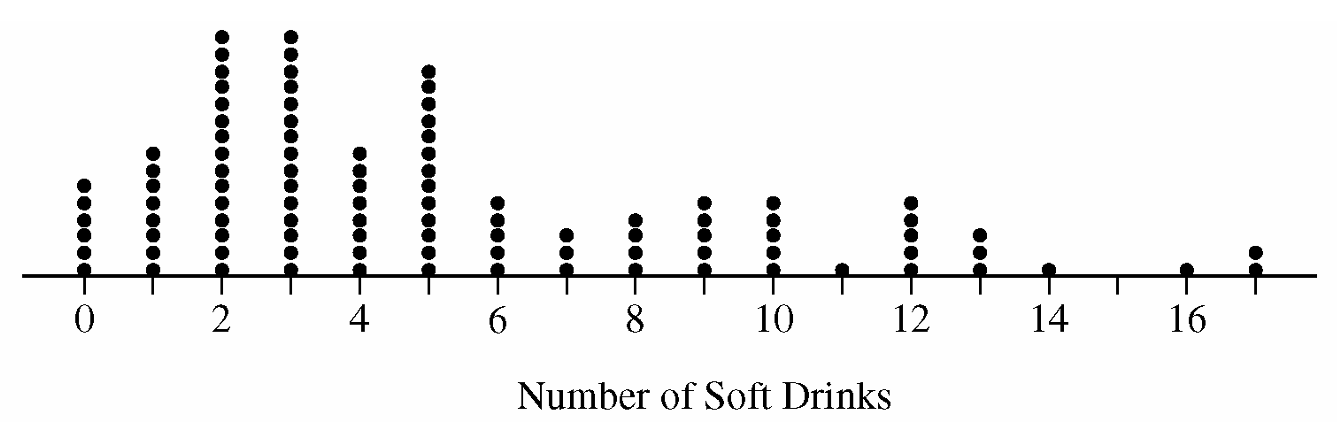
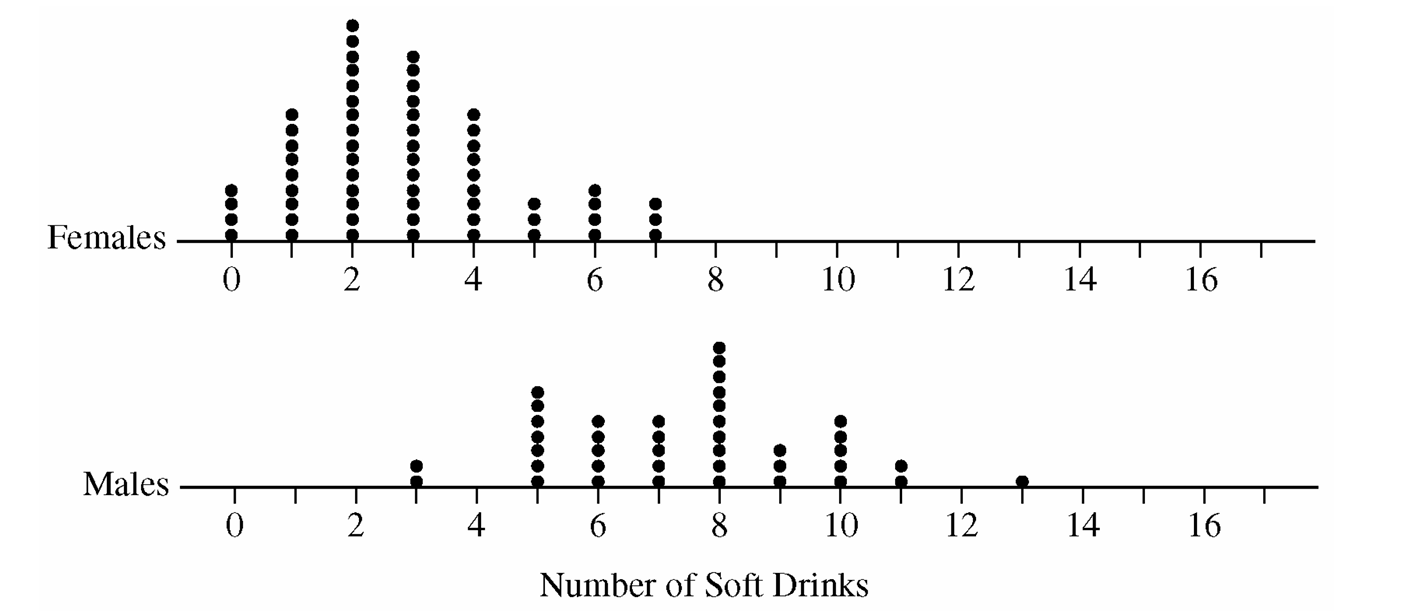
Based on the dotplots, there is a clear difference in the soft drink consumption patterns between genders. The dotplot for males indicates a visibly higher center (around 7-8 drinks) compared to the dotplot for females (centered around 2-3 drinks).
Because of this distinct separation between the two groups, a standard simple random sample like Peter’s will experience a large amount of variation as different samples will randomly capture varying proportions of males and females, producing a wider overall spread (standard deviation of 4.13).
By contrast, Rania’s stratified method guarantees that the sample consists of exactly 60% females and 40% males. The variability within each homogeneous gender group (1.80 for females and 2.22 for males) is much smaller than the overall variability of the mixed population.
Because stratification eliminates the between-group variation from the standard error calculation, Rania’s point estimator results in a substantially smaller estimated standard deviation.
Question
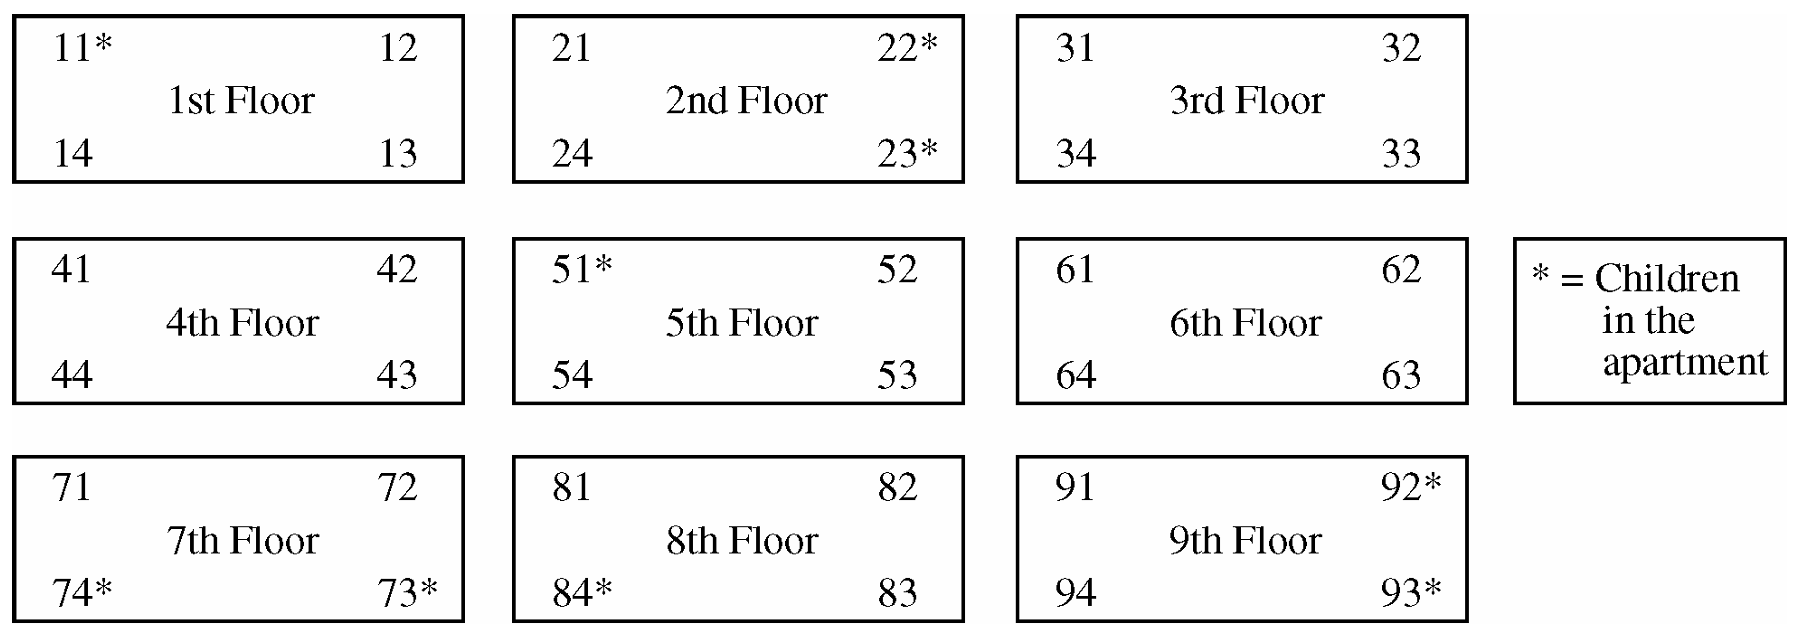
The figure below shows the floors of apartments in the building with their apartment numbers. Only the nine apartments indicated with an asterisk (*) have children in the apartment.
Most-appropriate topic codes (AP Statistics):
• Topic 1.11 — Random Sampling (Part b)
▶️ Answer/Explanation
(a)
To select a cluster sample of eight apartments using the floors as clusters, perform the following procedure:
Assign each of the nine floors a distinct integer label from $1$ to $9$.
Use a random number generator or a table of random digits to pick a random integer from $1$ to $9$. Select all four apartments on the corresponding floor.
Pick a second random integer from $1$ to $9$. If it matches the first number, ignore it and choose another until you get a different integer. Select all four apartments on that second floor.
The final sample will consist of the eight apartments located on the two uniquely chosen floors.
(b)
The direct advantage of using a stratified random sample over a cluster sample is that it guarantees both types of apartments—those with children and those without—are represented in the study.
Because carpet wear is highly likely to differ depending on whether children live in the apartment, it is vital to collect data on both scenarios to make an accurate overall assessment.
With the cluster sample, there is a distinct chance that the two floors randomly picked contain absolutely no apartments with children (such as floors 1, 3, or 5), entirely omitting a critical source of variation and blinding the owner to how well the carpet handles heavy child-related traffic.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 2.10 — The Binomial Distribution (Parts a, b)
• Topic 1.11 — Random Sampling (Part c)
▶️ Answer/Explanation
(a)
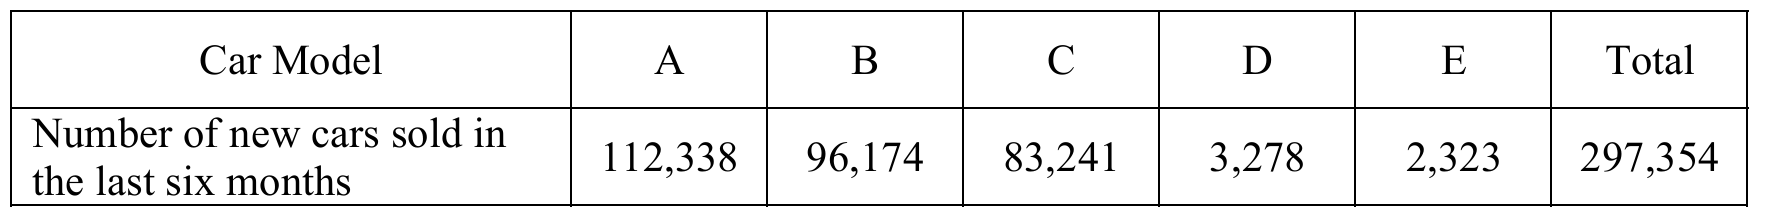
Because the total population ($297,354$) is overwhelmingly large compared to the sample size ($2,000$), we can treat this as a binomial distribution even though sampling is without replacement.
The probability of selecting a model E owner is $p = \dfrac{2,323}{297,354} \approx 0.007812$.
The sample size is $n = 2000$.
Expected number (Mean):
$\mu_E = n \times p = 2000 \times 0.007812 \approx 15.62$ owners
Standard Deviation:
$\sigma_E = \sqrt{n \times p \times (1-p)} = \sqrt{2000 \times 0.007812 \times (1 – 0.007812)} = \sqrt{15.49} \approx 3.93$ owners
(b)
For the reason given in part (a), the binomial distribution with $n = 2,000$ and $p \approx 0.0078$ can be used here. The probability that the sample would contain fewer than 12 owners of model E is calculated from the binomial distribution to be $\sum_{x=0}^{11} \binom{2,000}{x} (0.0078)^x (0.9922)^{2,000-x} \approx 0.147$. This probability is small enough that the result (fewer than 12 owners of model E in the sample) is not likely, but this probability is also not small enough to consider the result very unlikely.
This binomial probability can also be evaluated using a normal approximation. This is reasonable because $n \times p = (2,000) \times (0.0078) = 15.6$ is larger than 10 and $n(1 – p) = (2,000) \times (0.9922) = 1,984.4$ is much larger than 10. Using the mean and standard deviation from part (a) gives
$P(X \le 11) \approx P\left( Z < \dfrac{12.0 – 15.62}{3.94} \right) = P(Z < -0.92) = 0.179$.
(c)
To guarantee at least 12 owners from each model, the company should use a stratified random sampling method.
The researcher should use the five car models as the strata.
They can determine how many individuals they want to sample from each model (stratum) as long as every model’s assigned sample size is $12$ or greater, and all five sizes add up to exactly $2,000$.
Then, they simply perform five separate simple random samples—one within each specific car model’s list of owners—to achieve the decided quota for that model.
Question
Most-appropriate topic codes (AP Statistics):
▶️ Answer/Explanation
(a)
The administrators could number an alphabetical list of students from \(1\) to \(2,500\). They could then use a random number generator to select \(200\) unique random integers from \(1\) to \(2,500\). The students corresponding to those \(200\) numbers would be asked to participate in the survey.
(b)
One effective variable is school level (elementary, middle, high school). Students’ perceptions of food satisfaction likely differ by age and development level, making each school level a group with more internally consistent opinions than the district as a whole.
(c)
A primary advantage is reducing sampling variability by ensuring that each school level is represented proportionally in the survey. This ensures that the estimate of satisfaction is more precise because it accounts for the potential differences in opinion across different student age groups.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(1.12\) — Potential Problems with Sampling (Parts \(\mathrm{a}\), \(\mathrm{b}\), \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
Only 98 out of 500 families responded — that is a response rate of just \(\dfrac{98}{500} = 19.6\%\), meaning \(80.4\%\) did not reply at all.
For the survey results to be unbiased, we would need the 402 non-responding families to have similar opinions to those who did respond. But that is unlikely to be true — families who feel strongly in favour of year-round schooling may be much more motivated to respond, while those who oppose or feel indifferent may simply ignore the survey.
As a result, the observed proportion \(\dfrac{76}{98} \approx 77.6\%\) in favour likely overestimates the true proportion of all families who support the proposal. The school board’s conclusion that “most families prefer year-round schooling” may therefore be misleading.
(b)
No, taking an additional random sample of 500 families and combining the results would not be a suitable solution.
• The core problem is not the size of the sample — it is the low response rate in the original survey.
• The original 402 non-responses represent a biased portion of the data that will still be present in the combined sample, regardless of how the second sample turns out.
• If the second survey is conducted in the same way (mailed questionnaire with no follow-up), it is very likely to suffer from the same nonresponse bias, leaving the combined results just as unreliable.
Simply increasing the number of people surveyed does not fix bias — it only gives you a larger biased sample.
(c)
The school board should directly contact the 402 families who did not respond to the original survey, using a different mode of communication such as telephone calls or in-person visits, to obtain their opinions.
• This targets the exact group whose missing responses are causing the bias.
• Combining these newly obtained responses with the original 98 would give a much more complete and representative picture of opinion across all families in the district.
Alternatively, the board could design a new survey from scratch using in-person interviews or telephone calls to ensure a much higher response rate from the outset, reducing the opportunity for nonresponse bias to arise.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 1.9 — Comparisons of the Distributions for One Quantitative Variable (Part \(\mathrm{a}\))
• Topic 1.11 — Random Sampling (Part \(\mathrm{b}\))
• Topic 4.4 — Setting Up a Test for a Population Mean or Population Mean Difference (Part \(\mathrm{b}\))
▶️ Answer/Explanation
(a)
First, let’s organize the data for both groups:
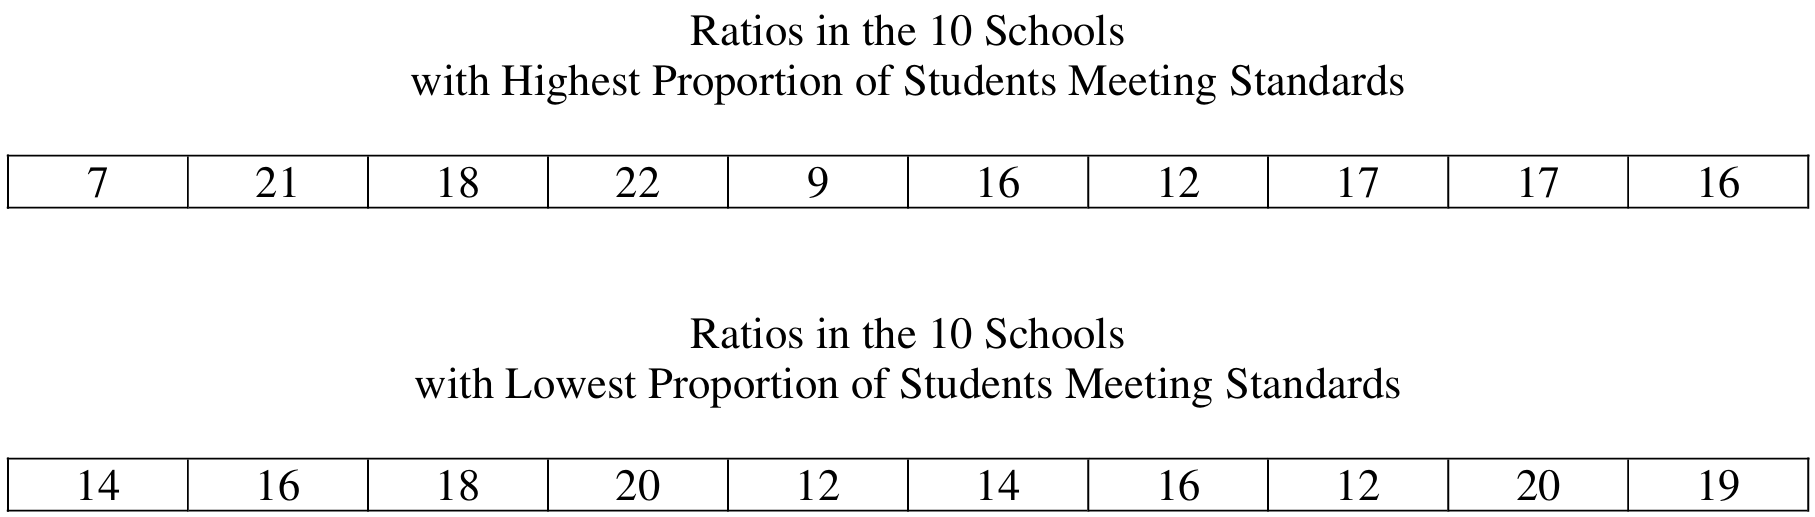
Highest Proportion group: \(7, 9, 12, 16, 16, 17, 17, 18, 21, 22\)
Lowest Proportion group: \(12, 12, 14, 14, 16, 16, 18, 19, 20, 20\)
The dotplots, displayed on a common scale from \(4\) to \(24\), are shown below:
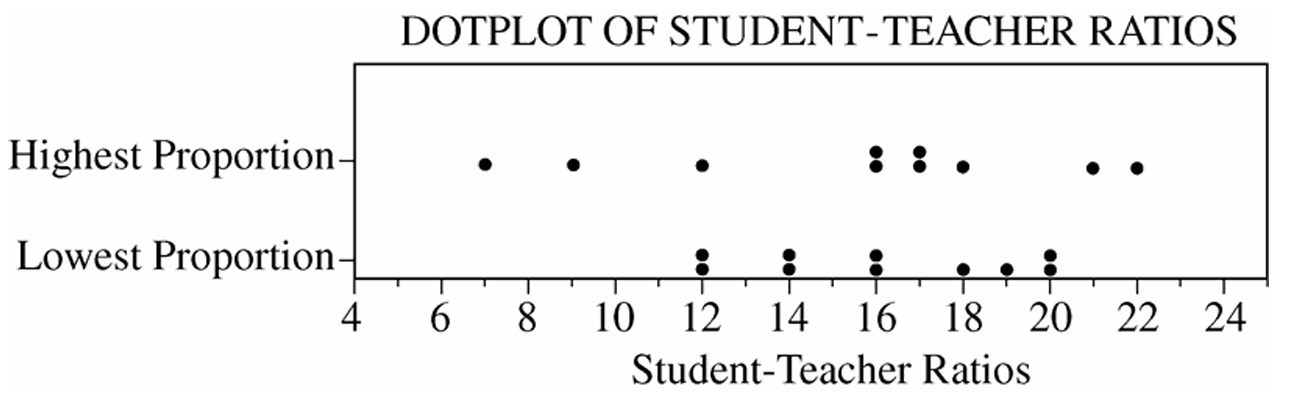
Similarities: The two distributions are centered at approximately the same place. The median for the Highest Proportion group is \(\dfrac{16+17}{2} = 16.5\) and the median for the Lowest Proportion group is \(\dfrac{16+16}{2} = 16\), so both centers are very close to \(16\).
Differences: The distribution for the Highest Proportion group is much more spread out (variable) than the distribution for the Lowest Proportion group. The range for the Highest Proportion group is \(22 – 7 = 15\), while the range for the Lowest Proportion group is only \(20 – 12 = 8\). In other words, the top schools show much greater variability in their student-to-teacher ratios compared to the bottom schools.
(b)
The two groups of schools are not random samples drawn from two larger populations of interest.
The group of 10 schools with the highest proportion of students meeting the standards is itself the entire population of such schools — it is not a random sample from some larger population of high-performing schools.
Similarly, the group of 10 schools with the lowest proportion is itself the complete population of the lowest-performing schools in the state — not a random sample from a larger population.
Since statistical inference is designed to generalize conclusions from a sample to a broader population, and these two groups are not random samples but rather complete populations defined by their extreme values, applying any inferential procedure (such as a two-sample \(t\)-test) to these data would be inappropriate. There is no larger population to generalize to.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 1.10 — The Investigative Question Revisited and Data Collection (Part \(\mathrm{a}\))
• Topic 1.11 — Random Sampling (Part \(\mathrm{b}\))
▶️ Answer/Explanation
(a)
A control group gives the researchers a baseline comparison group — without any dietary supplement — so they can measure whether glucosamine or chondroitin actually makes a difference beyond what would happen due to the normal aging process alone.
Without a control group, we could not tell whether any improvements in joint and hip health were caused by the supplements or simply by other factors such as the passage of time, veterinary care, or natural variation between dogs.
In this study specifically, the control group allows us to isolate the true effect of glucosamine and chondroitin on reducing canine osteoarthritis by comparing both treatment groups against untreated dogs under the same conditions.
\(\boxed{\text{Control group provides a baseline to determine whether the supplements are truly effective.}}\)
(b)
First, assign each of the 300 dogs a unique number from \(001\) to \(300\).
Then, use a random number generator (calculator, statistical software, or a random number table) to randomly select 100 numbers from \(001\) to \(300\), ignoring any repeats — the dogs corresponding to these 100 numbers are assigned to the glucosamine group.
From the remaining 200 dogs, randomly select another 100 numbers using the same process — these dogs are assigned to the chondroitin group.
The final 100 remaining dogs are assigned to the control group and receive no dietary supplement.
\(\boxed{\text{Randomly assign dogs numbered } 001\text{–}300 \text{ into three equal groups of 100 using a random number generator.}}\)
(c)
The blocking variable should be the one that has a stronger association with the response variable — joint and hip health — so that dogs within each block are as similar (homogeneous) as possible.
Breed of dog is associated with the size of the dog, and size is known to be related to joint and hip health — larger breeds tend to have more joint problems than smaller breeds, so breed is likely to create more variability in the response.
Clinic, on the other hand, is less likely to be strongly associated with joint and hip health because most large veterinary practices see a wide variety of dog breeds and sizes, so dogs across clinics would not be meaningfully more similar to each other than dogs across breeds.
Therefore, we should block on breed of dog, since it is more strongly related to joint and hip health and will reduce variability more effectively within each block.
\(\boxed{\text{Block on breed of dog, as it has a stronger relationship to joint and hip health than clinic.}}\)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 1.11 — Random Sampling (Part \(\mathrm{b}\))
• Topic 1.12 — Potential Problems with Sampling (Part \(\mathrm{b}\))
• Topic 1.10 — The Investigative Question Revisited and Data Collection (Part \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
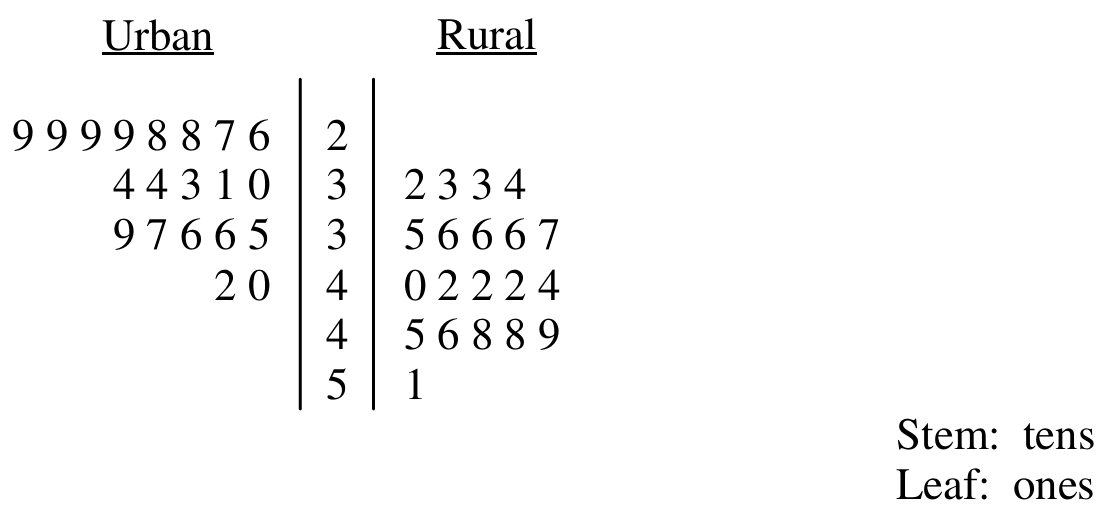
Reading the stemplot, the rural distribution is centered higher and is more spread out than the urban distribution.
For the rural students:
Mean \(\approx 40.45\) cal/kg
Median \(\approx 41\) cal/kg
Range \(= 19\)
SD \(\approx 6.04\)
IQR \(\approx 10\)
For the urban students:
Mean \(\approx 32.6\) cal/kg
Median \(\approx 32\) cal/kg
Range \(= 16\)
SD \(\approx 4.67\)
IQR \(\approx 7\)
So both the typical value and the spread are larger for the rural group. In terms of shape, the rural data look fairly symmetric and spread evenly between about 32 and 51 cal/kg, while the urban data appear skewed toward the larger values.
\( \boxed{\text{Rural: higher center and more spread; Urban: lower center, less spread, right-skewed}} \)
(b)
No. Each sample came from just one rural school and one urban school, so these two specific schools may not represent the much larger and more diverse population of all rural and urban ninth graders across the country. Because the schools themselves were not randomly chosen from all such schools, the results can’t be safely extended beyond these two schools.
\( \boxed{\text{No — only one school of each type was sampled, so results cannot be generalized nationally}} \)
(c)
Plan II is the better choice.
Both plans already adjust for body size by dividing calories by body weight, so that part is the same. The real issue is that a single day’s eating can be unusually high or low depending on what happened that day — a birthday party, a sick day, a weekend versus a school day, and so on. By recording food over a full 7-day period and averaging, Plan II smooths out this day-to-day variability and gives a more stable, precise picture of each student’s typical caloric intake.
\( \boxed{\text{Plan II — averaging over 7 days reduces day-to-day variability and gives a more precise estimate}} \)
Question
• Has a high school diploma
Most-appropriate topic codes (AP Statistics):
• Topic 3.3 — Constructing a Confidence Interval for a Population Proportion (Part \(\mathrm{b}\))
• Topic 1.11 — Random Sampling (Part \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
One issue is that random-digit dialing only reaches people who have a telephone. People without a high school diploma tend to have lower-paying jobs, so they may be less likely to be able to afford phone service. As a result, this group could be underrepresented in the sample.
\( \boxed{\text{Households without phones are missed, and these are more likely to lack a diploma, so the estimate may be too low}} \)
(b)
The margin of error for a proportion is
\( ME=z^*\sqrt{\dfrac{p(1-p)}{n}} \)
We want \(ME=0.03\) with \(95\%\) confidence, so \(z^*=1.96\), and we use the pilot estimate \(p=0.22\):
\( 0.03=1.96\sqrt{\dfrac{0.22(0.78)}{n}} \)
Solving for \(n\), first isolate the square root:
\( \sqrt{\dfrac{0.22(0.78)}{n}}=\dfrac{0.03}{1.96} \)
Square both sides:
\( \dfrac{0.22(0.78)}{n}=\left(\dfrac{0.03}{1.96}\right)^2 \)
Solve for \(n\):
\( n=\dfrac{0.22(0.78)}{\left(\dfrac{0.03}{1.96}\right)^2} \)
\( n=\left(\dfrac{1.96}{0.03}\right)^2(0.22)(0.78) \)
\( n\approx 732.47 \)
Since \(n\) must be a whole number and we need at least this many respondents, we round up:
\( \boxed{n=733\text{ respondents}} \)
(c)
A good approach here is stratified random sampling, using each state as a stratum. Within every state, a random sample of adult heads of households would be selected and surveyed, with the sample size in each state chosen based on the precision needed for that state. Once all the state-level samples are collected, the results can be combined to produce an overall national estimate.
\( \boxed{\text{Stratified random sampling — treat each state as a stratum and take a random sample within each state}} \)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.15 — Carrying Out a Chi-Square Test for Homogeneity or Independence (Part a)
• Topic 3.1 — Estimators (Part b)
• Topic 1.11 — Random Sampling (Part b)
▶️ Answer/Explanation
(a)
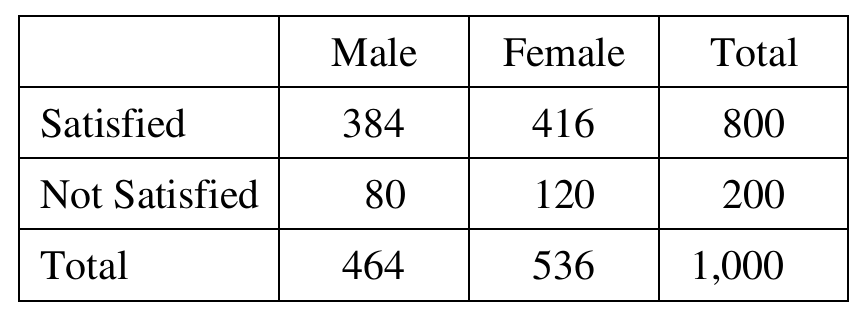
The appropriate procedure is a chi-square test for independence.
Hypotheses:
\(H_0\): Gender and satisfaction with hospital services are independent (no association).
\(H_a\): Gender and satisfaction with hospital services are not independent (there is an association)
Conditions:
— The sample is a random sample of 1,000 adult county residents.
— All expected cell counts must be at least 5.
Compute each:
\(E = \frac{(\text{row total})(\text{column total})}{\text{grand total}}\)
\(E(\text{Satisfied, Male}) = \dfrac{800 \times 464}{1000} = 371.2\)
\(E(\text{Satisfied, Female}) = \dfrac{800 \times 536}{1000} = 428.8\)
\(E(\text{Not Satisfied, Male}) = \dfrac{200 \times 464}{1000} = 92.8\)
\(E(\text{Not Satisfied, Female}) = \dfrac{200 \times 536}{1000} = 107.2\)
All expected counts are well above 5.
Test Statistic:
\(\chi^2 = \sum \frac{(O – E)^2}{E}\)
\(\chi^2 = \frac{(384 – 371.2)^2}{371.2} + \frac{(416 – 428.8)^2}{428.8} + \frac{(80 – 92.8)^2}{92.8} + \frac{(120 – 107.2)^2}{107.2}\)
\(\chi^2 = \frac{(12.8)^2}{371.2} + \frac{(-12.8)^2}{428.8} + \frac{(-12.8)^2}{92.8} + \frac{(12.8)^2}{107.2}\)
\(\chi^2 = 0.4413 + 0.3821 + 1.7655 + 1.5284 = 4.117\)
Degrees of freedom:
\(df = (r-1)(c-1) = (2-1)(2-1) = 1\)
P-value:
Using the \(\chi^2\) distribution with \(df = 1\):
\(p\text{-value} \approx 0.0424\)
Conclusion:
Since \(p\text{-value} = 0.0424 < \alpha = 0.05\), we reject \(H_0\). There is sufficient statistical evidence at the \(0.05\) significance level to conclude that there is an association between gender and satisfaction with hospital services for adult residents of this county.
\(\boxed{\chi^2 = 4.117,\quad df = 1,\quad p\text{-value} \approx 0.0424 \Rightarrow \text{Reject } H_0}\)
(b)
Yes, \(\dfrac{800}{1{,}000} = 0.80\) is a reasonable estimate for the proportion of all adult county residents who are satisfied with hospital services. The data were collected from a random sample of 1,000 adult county residents, which means the sample is likely representative of the population of all adult county residents. Because random sampling was used, the sample proportion \(\hat{p} = 0.80\) is an unbiased estimate of the true population proportion. Additionally, with a sample size of \(n = 1{,}000\), the estimate is based on a sufficiently large and randomly selected group, giving us reasonable confidence in its accuracy.
\(\boxed{\hat{p} = \frac{800}{1{,}000} = 0.80 \text{ is a reasonable estimate (random sample, large } n\text{)}}\)
Question
Many students believe that the food served in the dining hall needs improvement. Do you think that the quality of food served here needs improvement, even though that would increase the cost of the meal plan?
Most-appropriate topic codes (AP Statistics):
• Topic 1.12 — Potential Problems with Sampling (Parts a, b)
▶️ Answer/Explanation
(a)
Since the manager used a convenience sample — the first 100 students entering the cafeteria — bias may have been introduced because students who arrive at the dining hall early may have opinions about food quality that differ systematically from other dormitory residents who come later or not at all. For example, students who are very hungry or who have strong feelings about the food may be more likely to arrive early, making this group unrepresentative of all dormitory students.
To avoid this bias, the manager should have selected a random sample of 100 dormitory residents — for instance, using a simple random sample from a list of all dormitory residents, a stratified random sample by dormitory building, or a systematic random sample with a random starting point. Any of these approaches gives every dormitory resident a known, non-zero chance of being selected, which eliminates the selection bias introduced by the convenience sample.
(b)
The question as worded contains two sources of wording bias. First, the opening statement — “Many students believe that the food served in the dining hall needs improvement” — is leading because it tells respondents what other students think, which may pressure them to agree and respond “Yes” even if they do not truly feel that way.
Second, the phrase “even though that would increase the cost of the meal plan” introduces a second bias in the opposite direction, making students less likely to say “Yes” because they are reminded of a financial consequence. These two biases may push responses in opposite directions, making the results unreliable in either direction.
A better, more neutral wording would simply ask: “Do you think that the quality of food served in the dining hall needs improvement?” This removes the leading statement and the cost reminder, allowing students to respond based only on their true opinion about food quality.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.13 — Carrying Out a Test for the Difference Between Two Population Proportions (Part a)
• Topic 3.1 — Estimators (Part b)
• Topic 1.11 — Random Sampling (Part c)
• Topic 1.12 — Potential Problems with Sampling (Part c)
▶️ Answer/Explanation
(a)
Step 1: State hypotheses.
Let \(p_A\) = true proportion of banded birds on Island A, and \(p_B\) = true proportion of banded birds on Island B.
\(H_0: p_A – p_B = 0 \qquad H_a: p_A – p_B \neq 0\)
Step 2: Identify the test and check assumptions.
We use a two-sample \(z\)-test for a difference in proportions. The test statistic is:
\(z = \dfrac{\hat{p}_A – \hat{p}_B}{\sqrt{\hat{p}(1-\hat{p})\left(\dfrac{1}{n_1} + \dfrac{1}{n_2}\right)}}\)
The problem states the samples are random. Since the two islands are separate, the samples are independent. We check the large sample condition using the pooled estimate:
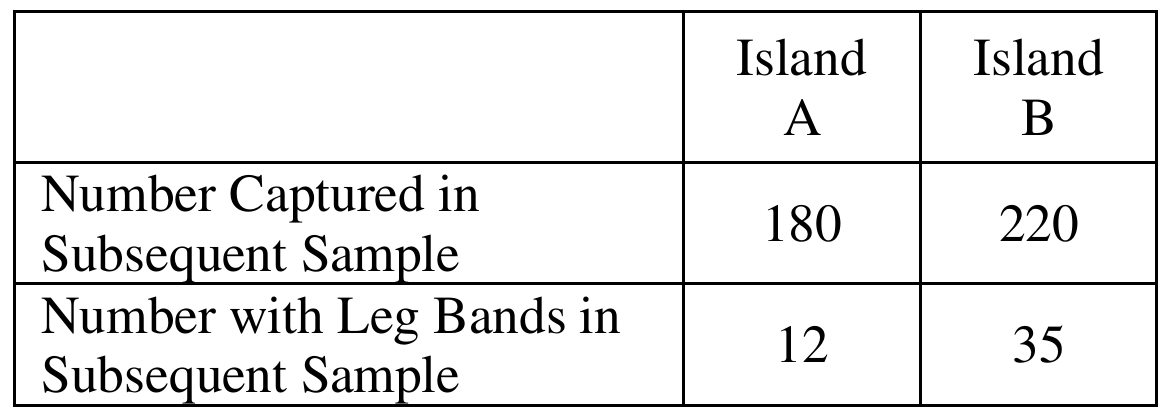
\(\hat{p} = \dfrac{n_A\hat{p}_A + n_B\hat{p}_B}{n_A + n_B} = \dfrac{12 + 35}{180 + 220} = \dfrac{47}{400} = 0.1175\)
Expected counts: \(n_A\hat{p} = 21.15,\quad n_A(1-\hat{p}) = 158.85,\quad n_B\hat{p} = 25.85,\quad n_B(1-\hat{p}) = 194.15\)
All expected counts are well above 5, so the large sample condition is satisfied.
Step 3: Compute the test statistic and p-value.
\(\hat{p}_A = \dfrac{12}{180} = 0.067 \qquad \hat{p}_B = \dfrac{35}{220} = 0.159\)
\(z = \dfrac{0.067 – 0.159}{\sqrt{\dfrac{(0.1175)(0.8825)}{180} + \dfrac{(0.1175)(0.8825)}{220}}} = \dfrac{-0.092}{\sqrt{0.00105}} = \dfrac{-0.092}{0.032} = -2.875\)
\(\text{p-value} = 2 \times P(Z < -2.875) \approx 0.00429\)
Step 4: State conclusion in context.
Since the p-value of \(0.00429\) is less than \(\alpha = 0.05\), we reject the null hypothesis. There is convincing statistical evidence that the proportions of banded birds on the two islands are different — Island B has a notably higher proportion of banded birds than Island A.
(b)
We use the capture-recapture logic: the proportion of banded birds in the subsequent sample estimates the proportion of banded birds in the whole population.
For Island A, the number of birds banded in the initial sample is \(n_I = 200\), and the proportion of banded birds observed in the subsequent sample is:
\(\hat{p}_S = \dfrac{12}{180} \approx 0.06667\)
Setting this equal to the fraction of banded birds in the population:
\(\hat{p}_S \approx \dfrac{n_I}{\text{population size}}\)
Solving for the estimated population size:
\(\text{Estimated population size} = \dfrac{n_I}{\hat{p}_S} = \dfrac{200}{12/180} = \dfrac{200 \times 180}{12} = \dfrac{36{,}000}{12} = \boxed{3{,}000 \text{ birds}}\)
(c)
Two concerns that should be addressed before assuming the captures can be treated as random samples are:
Concern 1 — Differential catchability: Some birds may be more likely to be captured than others — for example, slower, older, or less wary birds might be caught at a higher rate than the general population. If the same birds that were easy to capture in the initial sample are also more likely to appear in the subsequent sample, then banded birds would be overrepresented in the subsequent sample, leading us to underestimate the true population size.
Concern 2 — Behavioural change after banding: Birds that were captured and banded in the initial sample may become more trap-shy (avoiding capture in the future) or, conversely, may be more conspicuous to predators due to the bands, altering their survival or behaviour. If banded birds are less likely to be recaptured, we would overestimate the population size. In either case, if banding changes the birds’ behaviour or survival, the subsequent sample can no longer be treated as a true random sample of the population.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 1.11 — Random Sampling (Part c)
• Topic 1.12 — Potential Problems with Sampling (Part c)
▶️ Answer/Explanation
(a)
If volunteers who work together are all placed in the same program, there’s a risk that something specific to their workplace situation gets mixed up with the effect of the program itself. For example, suppose this group’s department recently had a deadline pushed back, which on its own would lower everyone’s stress level in that department regardless of which program they’re doing. If this entire group ends up in, say, the tai chi group, then the drop in stress they experience could mistakenly be credited to tai chi, when really it was caused by the lighter workload.
Random assignment fixes this issue. By randomly assigning volunteers to the two programs instead of letting groups choose, we spread people from this department across both the tai chi and yoga groups. This way, any unusual circumstance affecting that department’s stress levels — like the deadline change — gets “evened out” between the two treatment groups rather than being concentrated in just one. Randomization helps make sure the two groups are comparable at the start, so that any difference we see at the end can be attributed to the program rather than to some other confounding factor.
(b)
Yes, a control group would add useful information. Without one, the company could only compare tai chi to yoga directly — they could say which of the two programs led to a bigger drop in stress, but they couldn’t say whether either program actually caused a reduction in stress at all.
Here’s the issue: stress levels might naturally go down over a \(10\)-week period for reasons that have nothing to do with either program — for instance, if the overall work environment becomes less hectic during that time, everyone’s stress might drop a little just from that. A control group, which doesn’t participate in either program but still has its stress measured at the start and end of the \(10\) weeks, gives a baseline for what “no treatment” looks like under those same conditions.
By comparing each treatment group’s change in stress to the control group’s change, the company can tell how much of the reduction is actually attributable to tai chi or yoga specifically, rather than just background changes that would have happened anyway.
(c)
No, it is not reasonable to generalize these findings to all employees of the company. The participants in this study were volunteers, not a random sample of employees. People who choose to volunteer for a stress-reduction study might already be different from the typical employee — for example, they might be more motivated to manage their stress, more open to trying tai chi or yoga, or have more flexible schedules that let them give up part of their lunch hour.
Because the group wasn’t randomly selected from the entire employee population, there’s no guarantee that what works (or doesn’t work) for these volunteers would apply the same way to employees who didn’t volunteer. So while the random assignment within the study supports drawing cause-and-effect conclusions about tai chi versus yoga for people like these volunteers, it doesn’t justify extending those conclusions to the company as a whole.