
AP Statistics 2.1 Tabular and Graphical Representations for the Distributions of Two Categorical Variables- Exam Style Questions - FRQs - New Syllabus
Question
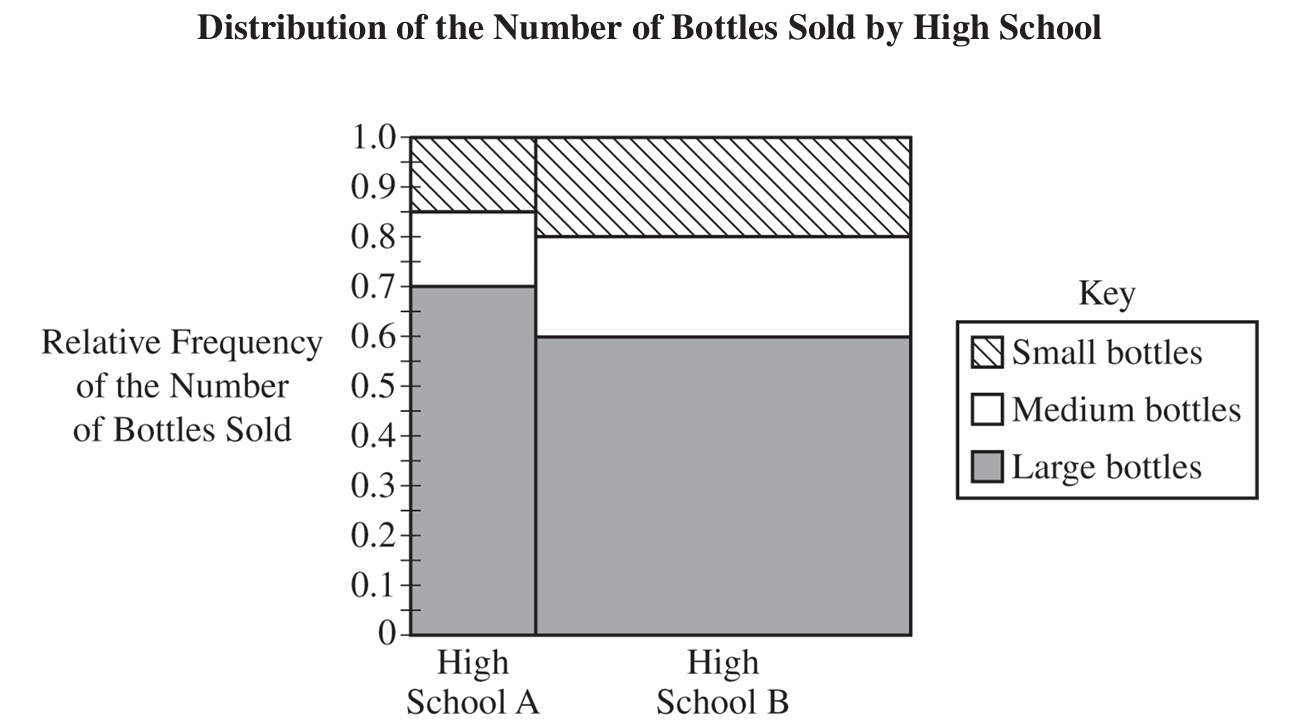
ii. Which of the two high schools sold a greater number of large bottles? Justify your answer.
Most-appropriate topic codes (AP Statistics):
• Topic \(2.2\) — Summary Statistics for Two Categorical Variables (Part \( \mathrm{b} \))
▶️ Answer/Explanation
(a)
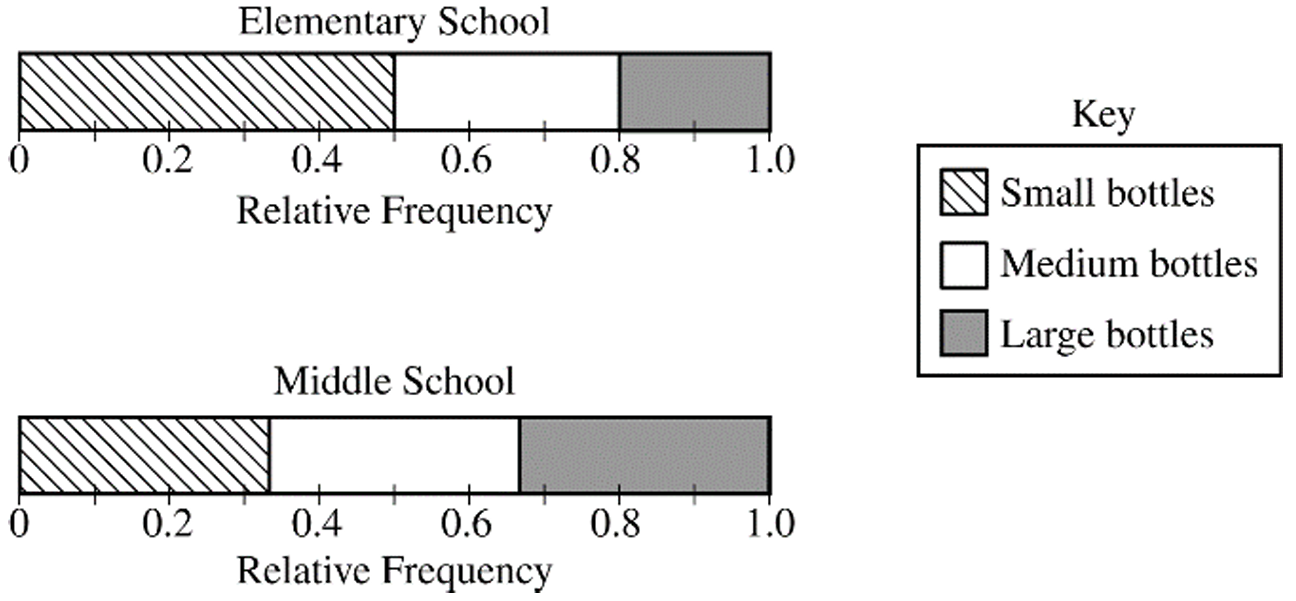
For the Elementary School bar graph, partition the segments at \(0.5\) for small bottles, \(0.8\) (\(0.5 + 0.3\)) for medium bottles, and \(1.0\) for large bottles.
For the Middle School bar graph, since the proportions are equal, partition the bar into three equal areas at approximately \(0.33\) and \(0.67\).
(b)
No, the elementary school administrator’s conclusion is incorrect.
Let \(x\) represent the total number of bottles sold by the elementary school.
This means the elementary school sold \(0.5x\) small bottles.
The middle school sold three times as many total bottles, which is \(3x\).
Since the proportion is equal across the three sizes, the middle school sold \(\frac{1}{3}(3x) = x\) small bottles.
Because \(x > 0.5x\), the middle school actually sold more small bottles than the elementary school.
(c)(i)
High School A sold a greater proportion of large bottles.
Looking at the y-axis of the mosaic plot, High School A’s proportion for large bottles is \(0.7\), which is greater than High School B’s proportion of \(0.6\).
(c)(ii)
High School B sold a greater number of large bottles.
In a mosaic plot, the total number of items is represented by the area of the segments.
Even though High School A had a larger proportion, the overall area of the rectangle representing large bottles for High School B is visibly larger than the area for High School A.
Question
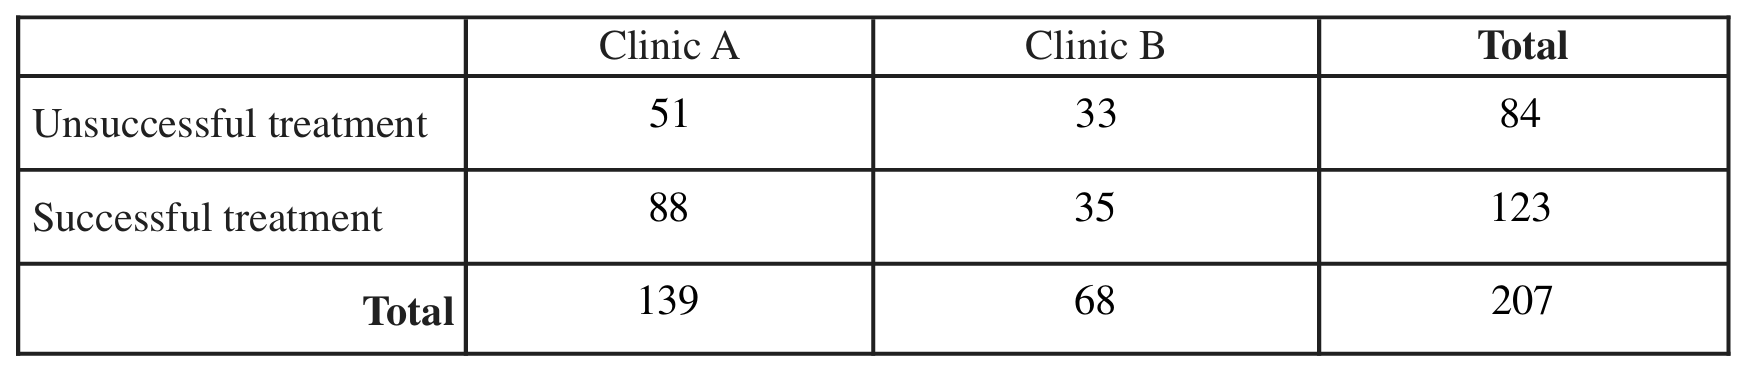
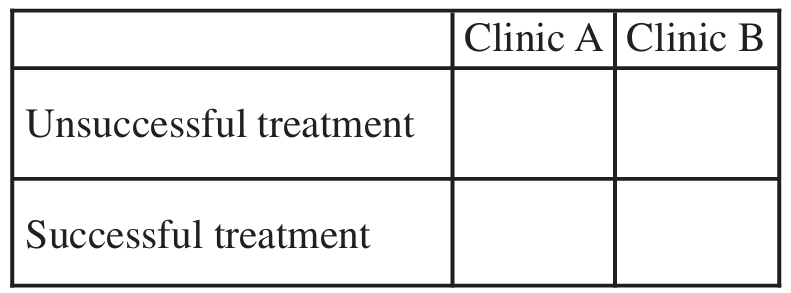
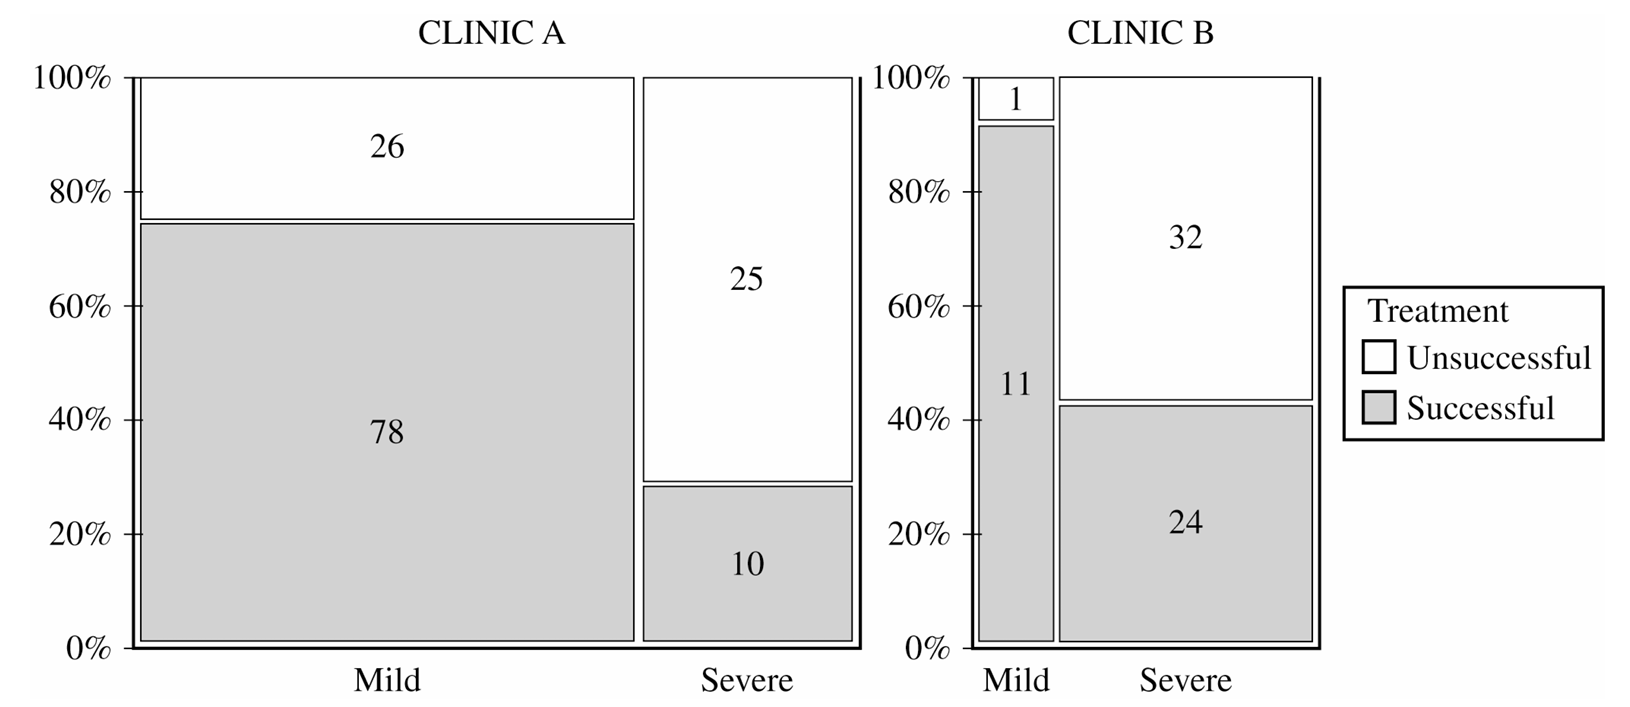
For mild allergy sufferers, Clinic B was more successful in treating allergies.
For severe allergy sufferers, Clinic B was more successful in treating allergies.
• Clinic B:
• Clinic B:
Most-appropriate topic codes (AP Statistics):
• Topic \(2.1\) — Tabular and Graphical Representations for the Distributions of Two Categorical Variables (Parts \( \mathrm{a} \), \( \mathrm{c} \))
• Topic \(2.2\) — Summary Statistics for Two Categorical Variables (Parts \( \mathrm{a} \), \( \mathrm{c} \), \( \mathrm{d} \))
▶️ Answer/Explanation
(a)(i)
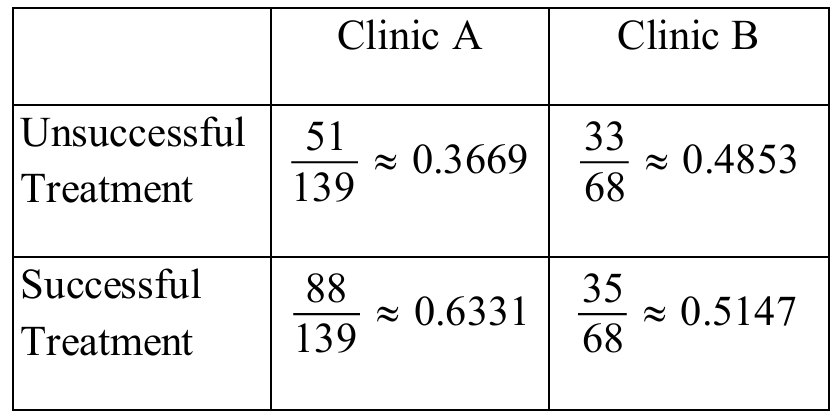
(a)(ii)
Clinic A is more successful. The relative frequency of successful treatments for Clinic A ($0.633$ or $63.3\%$) is greater than the relative frequency of successful treatments for Clinic B ($0.515$ or $51.5\%$).
(b)
No. The researchers selected random samples of patient records, which means this is an observational study, not a randomized experiment. Because patients were not randomly assigned to Clinic A or Clinic B, we cannot establish a cause-and-effect relationship due to the potential presence of confounding variables.
(c)(i)
• Clinic A: Mild allergies are treated more successfully. The success rate for mild is $78 / (78 + 26) = 75\%$, while the success rate for severe is $11 / (11 + 24) = 31.4\%$.
• Clinic B: Mild allergies are treated more successfully. The success rate for mild is $32 / (32 + 1) = 97\%$, while the success rate for severe is $10 / (10 + 25) = 28.6\%$.
(c)(ii)
• Clinic A: Mild allergies are more likely to be treated. Clinic A treated 104 mild cases ($78+26$) compared to only 35 severe cases ($11+24$).
• Clinic B: Severe allergies are more likely to be treated. Clinic B treated 35 severe cases ($10+25$) compared to only 33 mild cases ($32+1$).
(d)
The conclusion is different because of Simpson’s Paradox. Clinic A’s overall success rate is higher because it treats a much larger proportion of mild allergy cases, which naturally have a higher success rate regardless of the clinic. Conversely, Clinic B treats a higher proportion of severe cases, which brings its overall average down, even though it performs better than Clinic A within each specific severity group.
Question
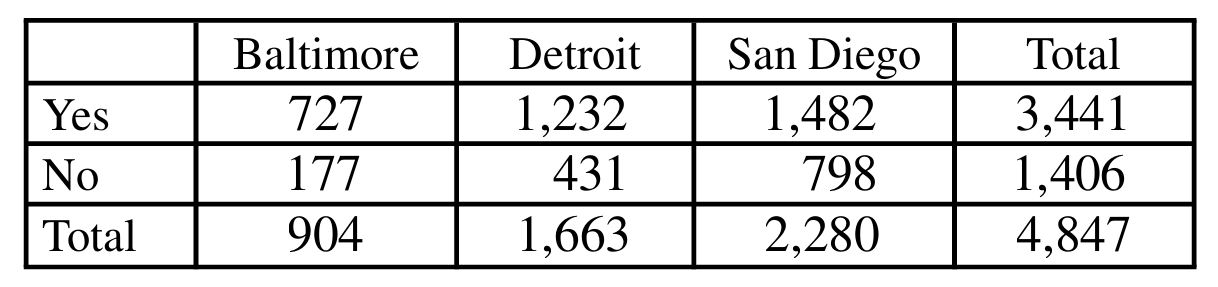
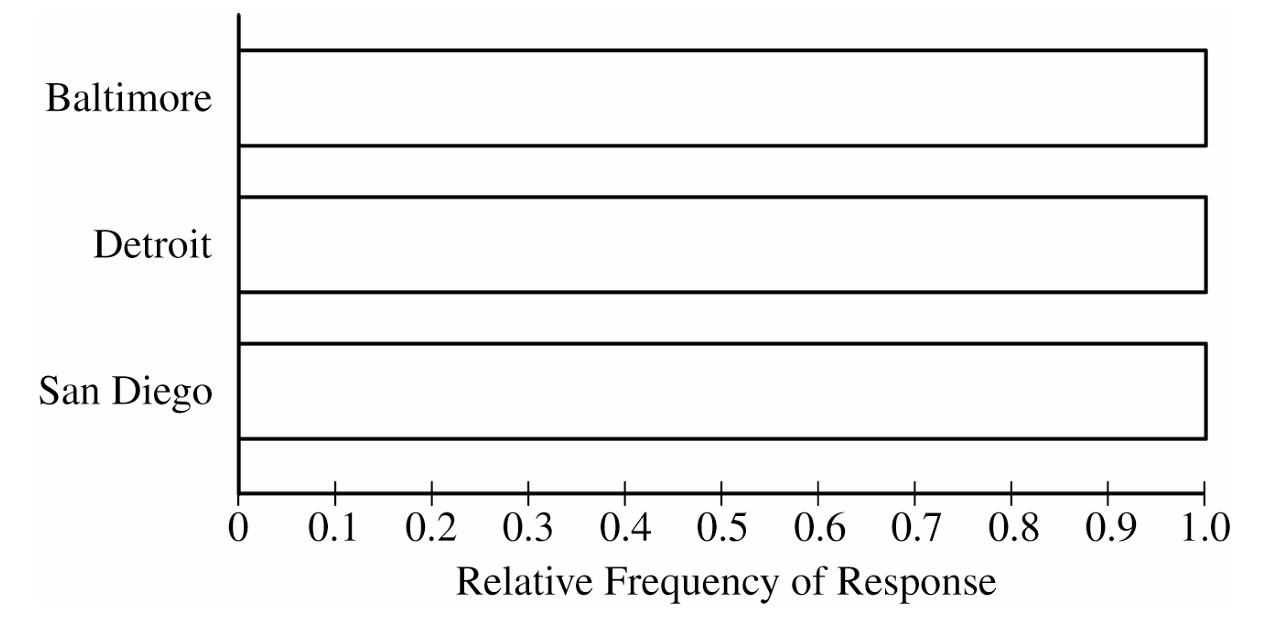
ii. Which city had the smallest proportion of teens who consumed a soft drink in the previous week? Determine the value of the proportion.
ii. Identify the hypotheses of the test.
Most-appropriate topic codes (AP Statistics):
• Topic \(2.2\) — Summary Statistics for Two Categorical Variables (Parts \( \mathrm{a} \), \( \mathrm{b} \))
• Topic \(3.14\) — Setting Up a Chi-Square Test for Homogeneity or Independence (Part \( \mathrm{c} \))
▶️ Answer/Explanation
(a)
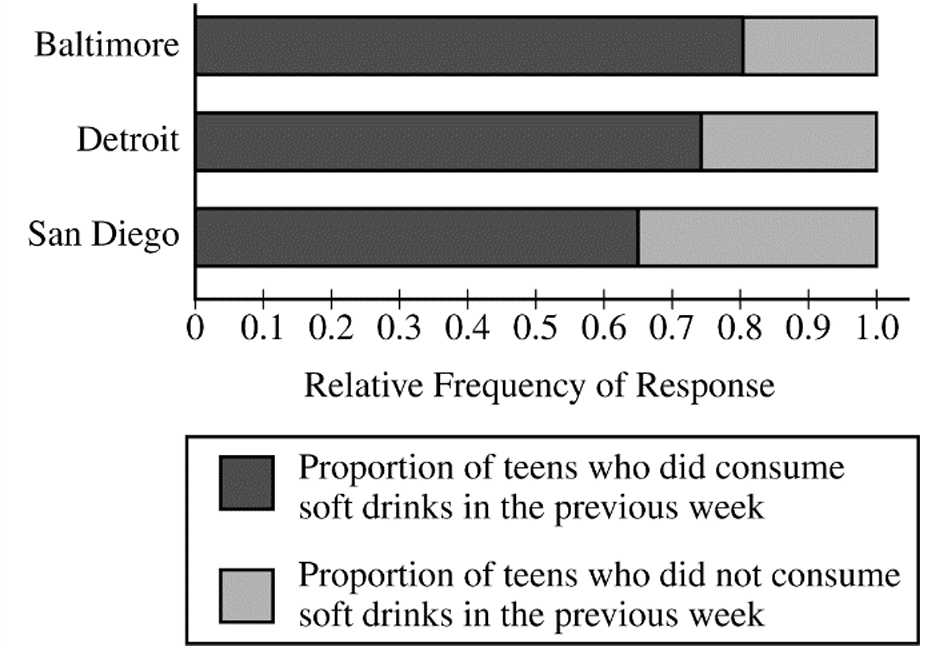
No, the researcher’s claim is incorrect because comparing mere counts is meaningless when the sample sizes across the cities are unequal. Instead, we must compare proportions: the proportion for Baltimore is \( \frac{727}{904} \approx 0.804 \), which is actually greater than the proportions for Detroit (\( \frac{1232}{1663} \approx 0.741 \)) and San Diego (\( \frac{1482}{2280} = 0.65 \)).
(b)(i)
To construct the segmented bar chart, you would calculate the relative frequencies for “Yes” and “No” for each city and stack them so each bar reaches \(1.0\) on the vertical axis. For example, Baltimore’s “Yes” segment would extend up to \( 0.804 \), with the “No” segment filling the rest up to \( 1.0 \).
(b)(ii)
San Diego had the smallest proportion of teens who consumed a soft drink, with a value of \( \frac{1482}{2280} = 0.65 \).
(c)(i)
A chi-square test for homogeneity is the appropriate inference procedure because we are investigating whether the distribution of a single categorical variable (consuming a soft drink) is the same across multiple independent populations (the three cities).
(c)(ii)
The null hypothesis \(H_0\) is that there is no difference in the true proportion of all teens who consumed a soft drink in the past week across the three cities. The alternative hypothesis \(H_a\) is that there is at least one difference in the proportion of all teens who consumed a soft drink in the past week across the three cities.
Question
- Are you an on campus student or an off campus student?
- In how many extracurricular activities do you participate?
\(H_0\): There is no association between residential status and level of participation in extracurricular activities among the students at the university.
\(H_a\): There is an association between residential status and level of participation in extracurricular activities among the students at the university.
Most-appropriate topic codes (AP Statistics):
• Topic \(3.14\) — Setting Up a Chi-Square Test for Homogeneity or Independence (Part \( \mathrm{c} \))
• Topic \(3.15\) — Carrying Out a Chi-Square Test for Homogeneity or Independence (Part \( \mathrm{c} \))
▶️ Answer/Explanation
(a)
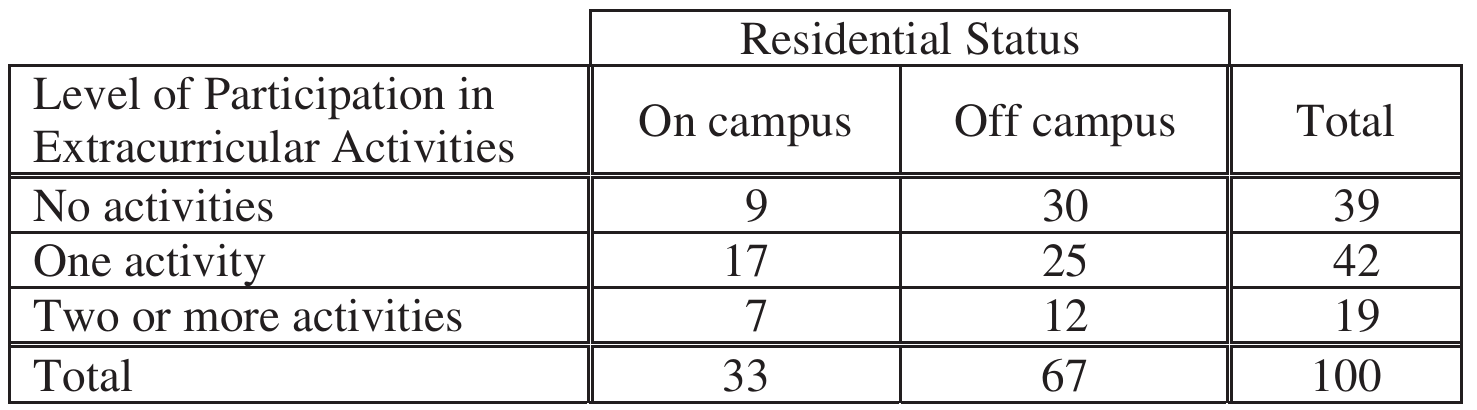
For on campus students, “at least one activity” means one activity or two or more activities, so we add those counts and divide by the total number of on campus students:
\(\hat{p}_{\text{on}} = \dfrac{17 + 7}{33} = \dfrac{24}{33} \approx 0.727\)
For off campus students, we do the same:
\(\hat{p}_{\text{off}} = \dfrac{25 + 12}{67} = \dfrac{37}{67} \approx 0.552\)
\(\boxed{\hat{p}_{\text{on}} \approx 0.727, \quad \hat{p}_{\text{off}} \approx 0.552}\)
(b)
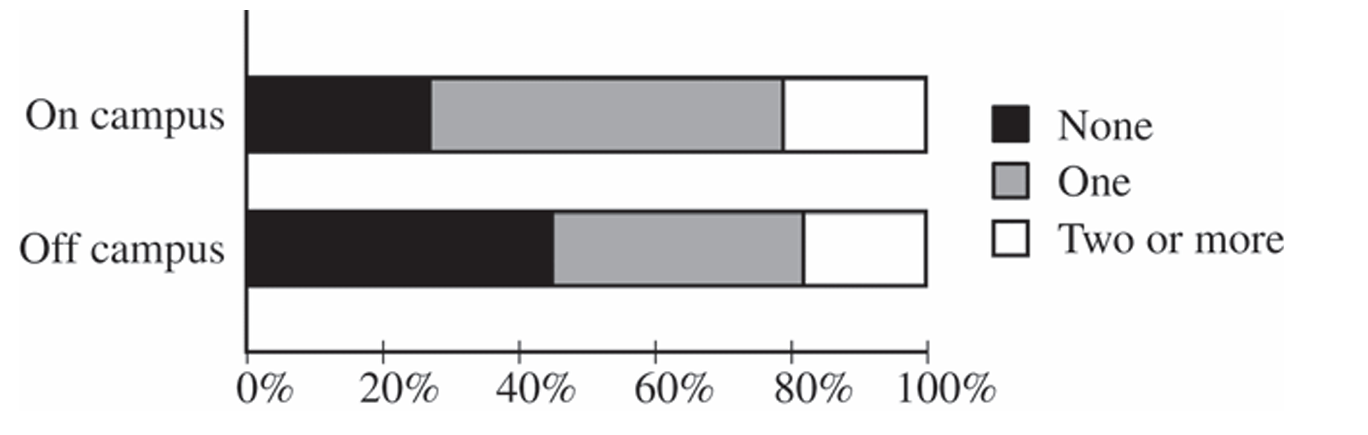
Looking at the segmented bar graph, on campus residents appear more likely to participate in extracurricular activities than off campus residents. Specifically, on campus students have a higher proportion participating in one activity (about \(51.5\%\) vs. \(37.3\%\)) and a lower proportion participating in no activities (about \(27.3\%\) vs. \(44.8\%\)). The proportions participating in two or more activities are fairly similar between the two groups (on campus: \(\approx 21.2\%\), off campus: \(\approx 17.9\%\)).
(c)
The \(p\)-value of \(0.23\) is greater than conventional significance levels such as \(\alpha = 0.05\) or \(\alpha = 0.10\). Because the \(p\)-value is large, we fail to reject the null hypothesis \(H_0\).
The sample data do not provide sufficient evidence to conclude that there is an association between residential status and level of participation in extracurricular activities among all students at the university.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 2.7 — Independent Events and Unions of Events (Part b)
• Topic 2.1 — Tabular and Graphical Representations for the Distributions of Two Categorical Variables (Part c)
▶️ Answer/Explanation
(a)
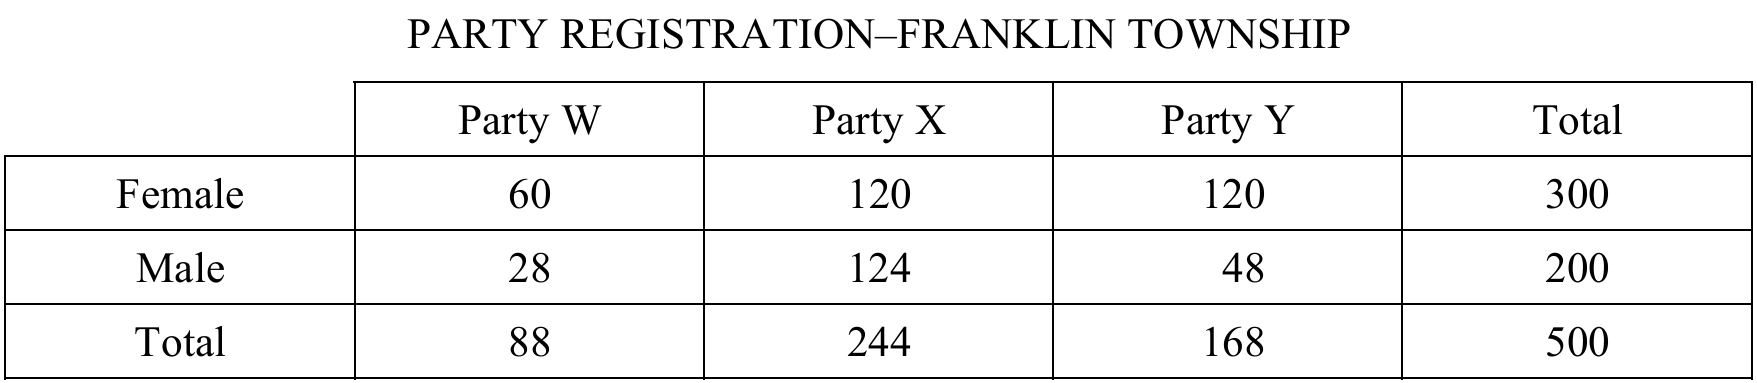
We need to find the conditional probability that a voter is registered for Party Y, given they are male. Looking only at the “Male” row, there are $200$ total males, and $48$ of them are registered for Party Y.
$P(\text{Party Y} \mid \text{Male}) = \frac{48}{200} = 0.24$
(b)
No, the events “is a male” and “is registered for Party Y” are not independent.
Two events $A$ and $B$ are independent if $P(A \mid B) = P(A)$. Let’s compare the conditional probability from part (a) to the overall marginal probability of being registered for Party Y.
$P(\text{Party Y}) = \frac{168}{500} = 0.336$
Since $P(\text{Party Y} \mid \text{Male}) = 0.24$ and $P(\text{Party Y}) = 0.336$, the probabilities are not equal ($0.24 \neq 0.336$). Knowing that a randomly selected voter is male changes the probability that they are registered for Party Y, so the events are dependent.
(c)
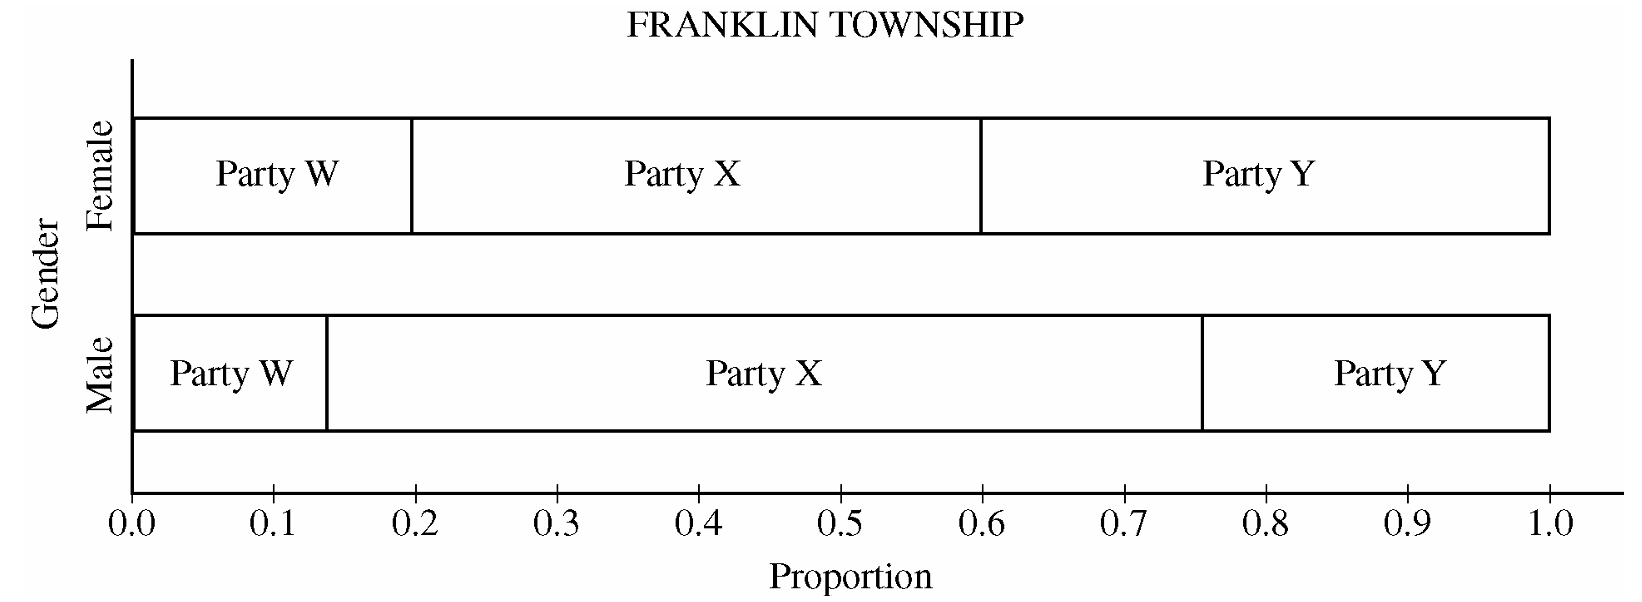
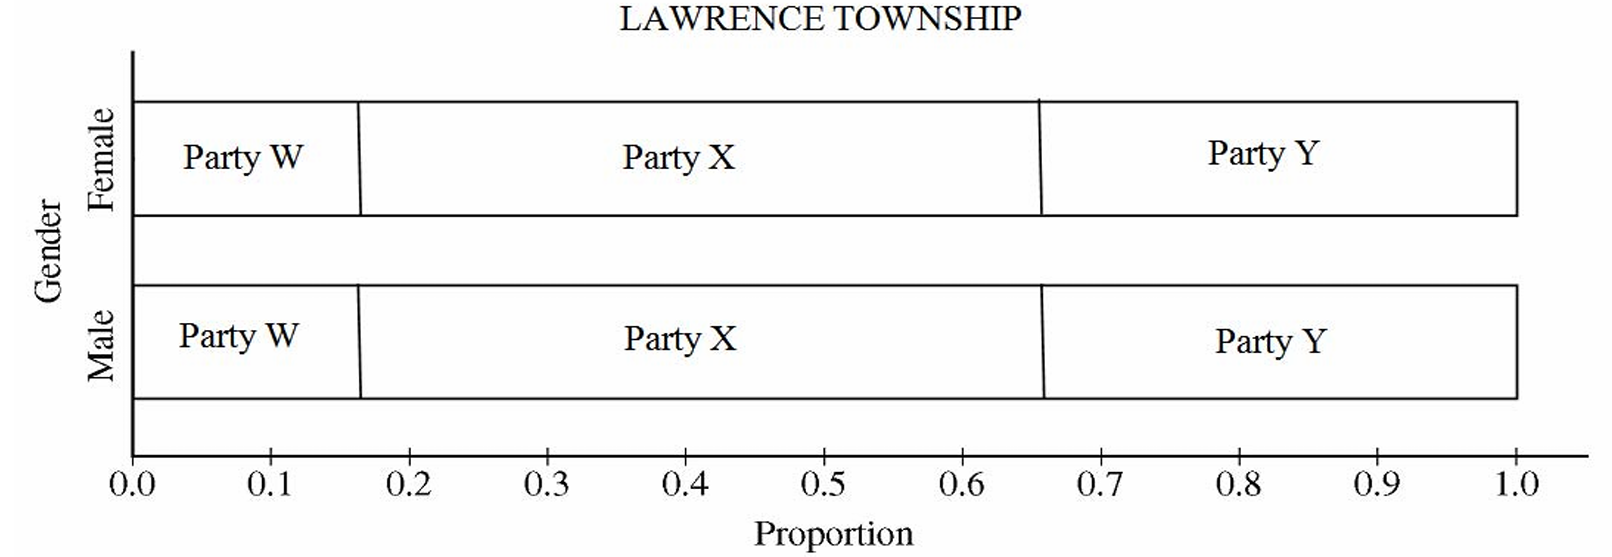
Because party registration is independent of gender in Lawrence Township, the distribution of party registration for both males and females must be identical to the overall marginal distribution of the town.
We first calculate the overall proportions for each party (which are the same as Franklin Township’s overall proportions):
Party W: $\frac{88}{500} = 0.176$
Party X: $\frac{244}{500} = 0.488$
Party Y: $\frac{168}{500} = 0.336$
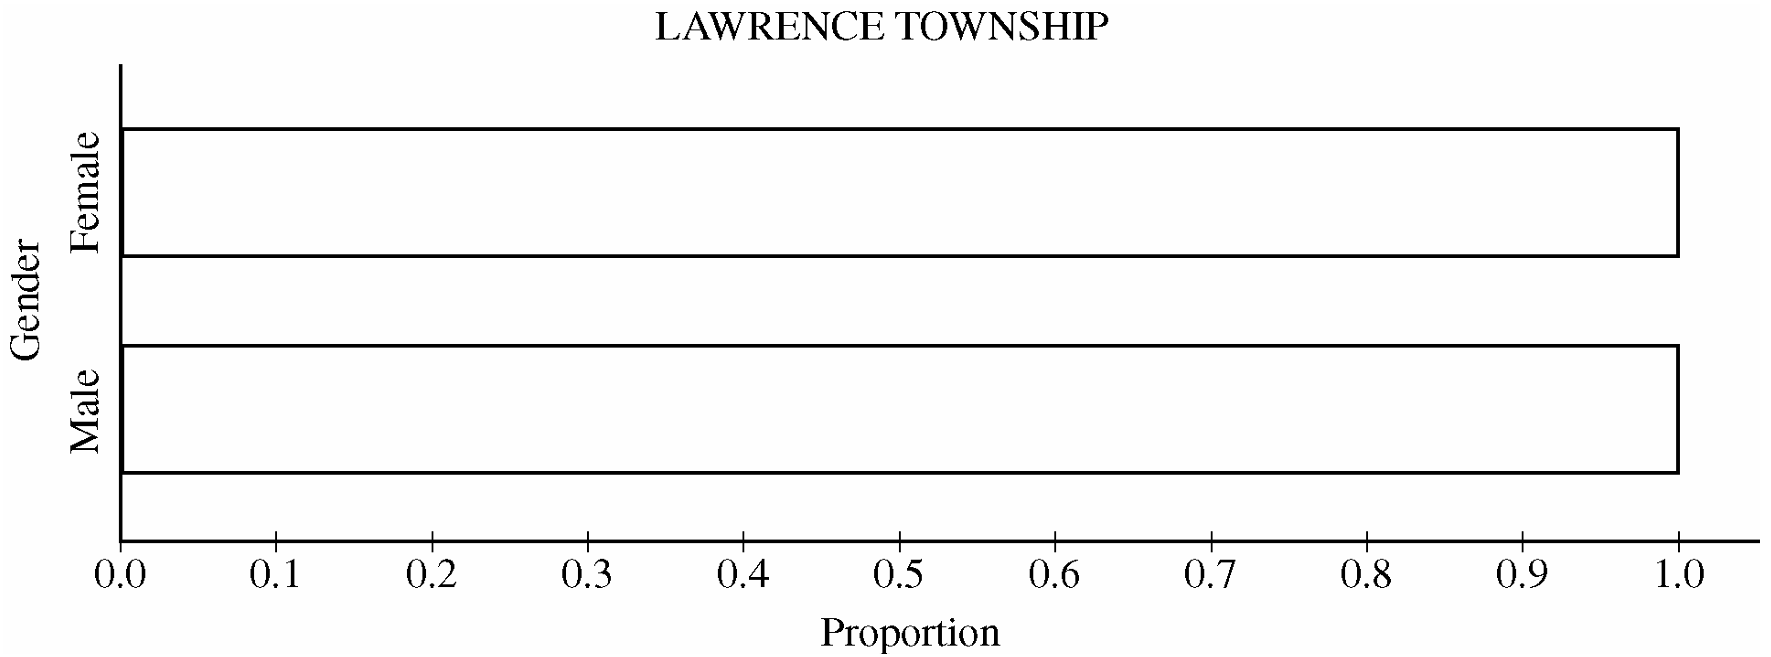
To complete the segmented bar graph, you would draw identical bars for both the Male and Female categories with the following dividing lines:
• The segment for Party W starts at $0.0$ and ends at $0.176$.
• The segment for Party X starts at $0.176$ and ends at $0.176 + 0.488 = 0.664$.
• The segment for Party Y starts at $0.664$ and extends to $1.0$.
Question
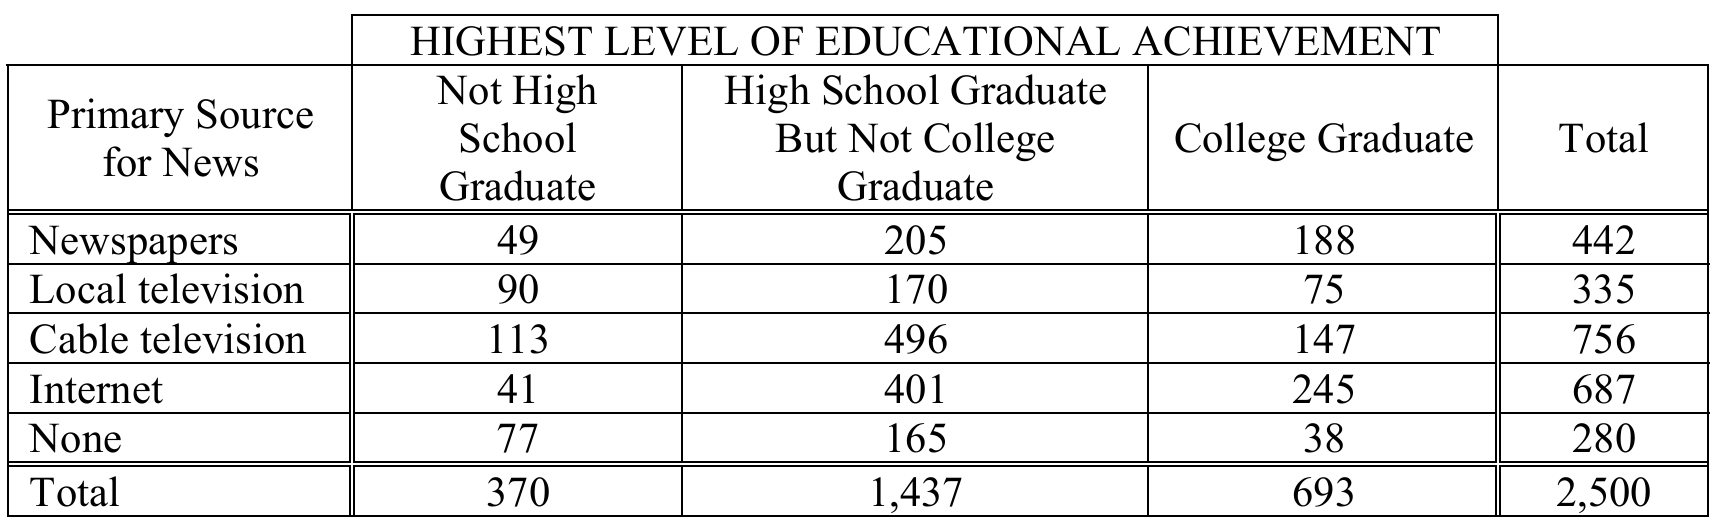
(d) The company wants to conduct a statistical test to investigate whether there is an association between educational achievement and primary source for news for adults in the city. What is the name of the statistical test that should be used?
Most-appropriate topic codes (AP Statistics):
• Topic \(2.6\) — Conditional Probability (Part \(\mathrm{b}\))
• Topic \(2.7\) — Independent Events and Unions of Events (Parts \(\mathrm{a}\), \(\mathrm{c}\))
• Topic \(3.14\) — Setting Up a Chi-Square Test for Homogeneity or Independence (Part \(\mathrm{d}\))
▶️ Answer/Explanation
(a)
Let \(C\) = event that the adult is a college graduate, and \(I\) = event that the adult obtains news primarily from the internet.
Using the Addition Rule:
\(P(C \cup I) = P(C) + P(I) – P(C \cap I)\)
Reading the values directly from the table:
\(P(C) = \frac{693}{2500}, \qquad P(I) = \frac{687}{2500}, \qquad P(C \cap I) = \frac{245}{2500}\)
\(P(C \cup I) = \frac{693}{2500} + \frac{687}{2500} – \frac{245}{2500} = \frac{693 + 687 – 245}{2500} = \frac{1135}{2500}\)
\(\boxed{P(C \cup I) = \frac{1135}{2500} = 0.454}\)
Don’t forget to subtract the overlap — college graduates who use the internet get counted in both the college graduate total and the internet total, so we subtract them once to avoid double-counting.
(b)
We want the conditional probability that an adult obtains news from the internet, given that the adult is a college graduate. From the table, among the 693 college graduates, 245 primarily use the internet:
\(P(I \mid C) = \frac{P(C \cap I)}{P(C)} = \frac{\dfrac{245}{2500}}{\dfrac{693}{2500}} = \frac{245}{693}\)
\(\boxed{P(I \mid C) = \frac{245}{693} \approx 0.354}\)
This is a conditional probability — we’ve already restricted our pool to only the 693 college graduates, so 693 becomes the new denominator. The 2,500 total cancels out entirely.
(c)
Two events are independent if and only if \(P(A \cap B) = P(A) \cdot P(B)\), which is equivalent to checking whether \(P(I \mid C) = P(I)\).
From the table:
\(P(I) = \frac{687}{2500} = 0.275\)
\(P(I \mid C) = \frac{245}{693} \approx 0.354\)
Since \(P(I \mid C) \approx 0.354 \neq 0.275 = P(I)\), the two events are not independent.
We can also verify using the multiplication rule directly:
\(P(C) \cdot P(I) = \frac{693}{2500} \times \frac{687}{2500} = \frac{476{,}091}{6{,}250{,}000} \approx 0.0762\)
\(P(C \cap I) = \frac{245}{2500} = 0.098\)
Since \(0.098 \neq 0.0762\), the events are confirmed to be not independent. In real terms, college graduates are noticeably more likely to get their news from the internet than the general adult population — that difference in rates is exactly what “not independent” means here.
(d)
The appropriate test is the Chi-Square Test of Association (or Independence).
This test is used when we want to determine whether there is an association between two categorical variables — here, educational achievement (3 categories) and primary news source (5 categories).
The degrees of freedom are calculated as:
\(\text{df} = (\text{number of rows} – 1) \times (\text{number of columns} – 1)\)
\(\text{df} = (5 – 1) \times (3 – 1) = 4 \times 2 = \boxed{8}\)
There are 5 rows (news source categories) and 3 columns (education levels), not counting the totals row and column. The degrees of freedom formula captures how many cells in the table are “free to vary” once the row and column totals are fixed.
Question
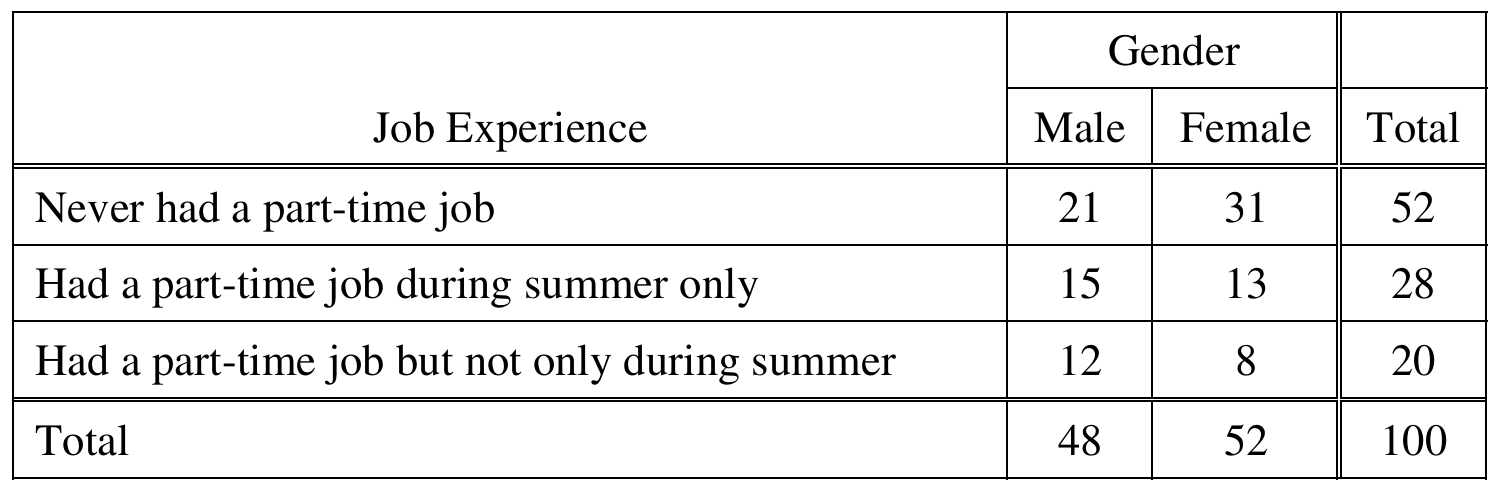
Most-appropriate topic codes (AP Statistics):
• Topic \(2.2\) — Summary Statistics for Two Categorical Variables (Part \(\mathrm{b}\))
• Topic \(3.14\) — Setting Up a Chi-Square Test for Homogeneity or Independence (Part \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
First, convert the raw counts to percentages within each gender so that males and females are directly comparable:
For Males \((n = 48)\):
• Never had a part-time job: \(\dfrac{21}{48} \approx 43.8\%\)
• Part-time job during summer only: \(\dfrac{15}{48} \approx 31.2\%\)
• Part-time job, not only during summer: \(\dfrac{12}{48} = 25.0\%\)
For Females \((n = 52)\):
• Never had a part-time job: \(\dfrac{31}{52} \approx 59.6\%\)
• Part-time job during summer only: \(\dfrac{13}{52} = 25.0\%\)
• Part-time job, not only during summer: \(\dfrac{8}{52} \approx 15.4\%\)
A side-by-side bar graph (or segmented bar graph) should be drawn with the three job-experience categories on the horizontal axis, percentage on the vertical axis, and separate bars (or segments) for Male and Female within each category. All axes must be labeled.
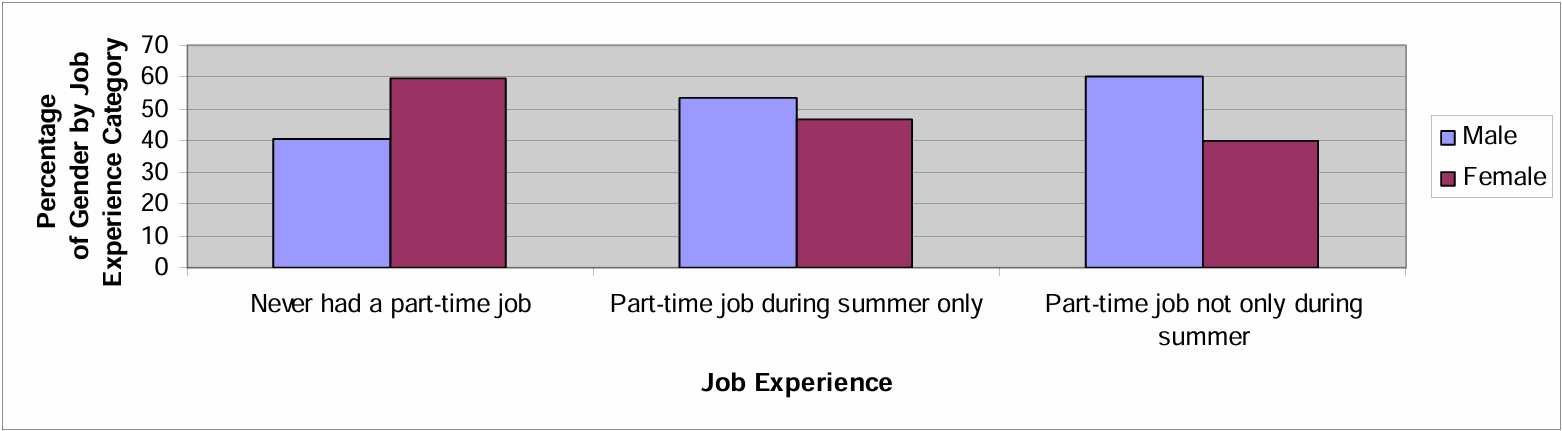
(b)
Looking at the bar graph, females were considerably more likely than males to have never had a part-time job — about \(59.6\%\) of females compared with \(43.8\%\) of males fall into that category.
On the other hand, males were more likely than females to have had a part-time job during the summer only (\(31.2\%\) vs. \(25.0\%\)), and more likely to have had a part-time job that was not only during the summer (\(25.0\%\) vs. \(15.4\%\)).
If there were no association between gender and job experience, we’d expect the bars for males and females to be roughly the same height in each category — but they clearly aren’t, so the sample data suggest there is an association between gender and job experience.
(c)
The appropriate test of significance is the chi-square test of association (or independence).
The chi-square test statistic is:
\( \chi^2 = \sum \frac{(\text{observed} – \text{expected})^2}{\text{expected}} \)
The null and alternative hypotheses are:
\(H_0\): There is no association between gender and job experience (for the population of high school seniors in the district).
\(H_a\): There is an association between gender and job experience (for the population of high school seniors in the district).
Equivalently:
\(H_0\): Gender and job experience are independent.
\(H_a\): Gender and job experience are not independent.
Since we have two categorical variables each with multiple categories, the chi-square test of association/independence is the correct choice — a two-sample \(z\)-test for proportions only compares two groups on a binary outcome, and wouldn’t capture all three job-experience categories at once.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 2.6 — Conditional Probability (Part b)
• Topic 2.7 — Independent Events and Unions of Events (Part c)
• Topic 2.2 — Summary Statistics for Two Categorical Variables (Part a)
▶️ Answer/Explanation
(a)
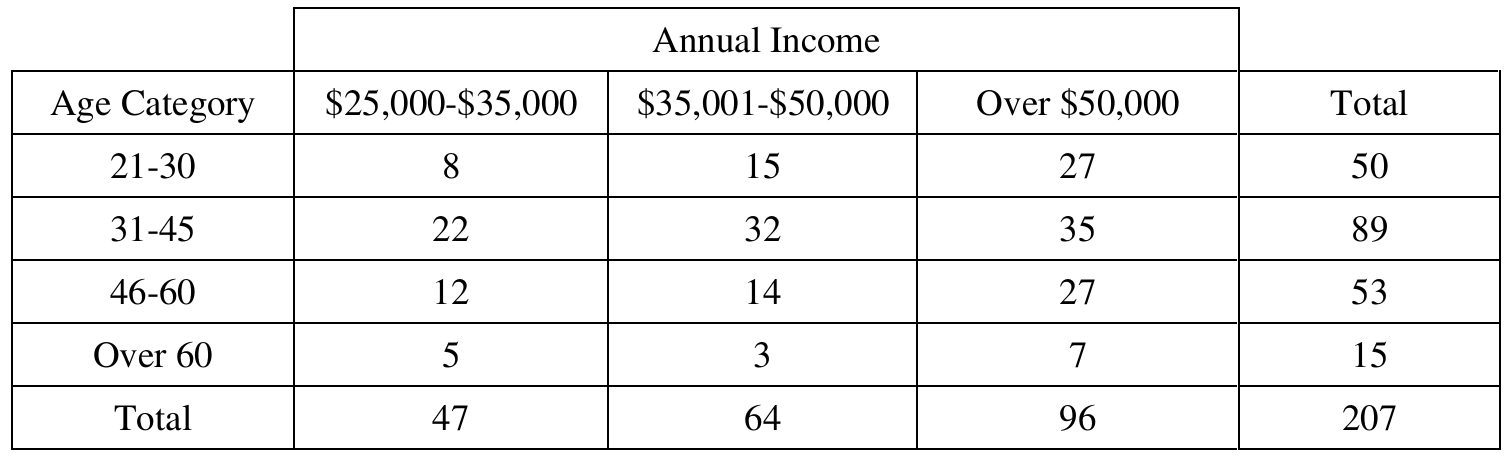
We want the probability that a randomly selected person from the sample falls in the 31–45 age category.
The total number of people in the sample is 207, and the number in the 31–45 age group is 89.
\( P(\text{age } 31\text{–}45) = \frac{89}{207} \approx 0.42995 \)
\(\boxed{P(\text{age } 31\text{–}45) \approx 0.4300}\)
(b)
We now want the conditional probability that a person is in the 31–45 age category, given that their income is over \(\$50{,}000\).
From the table, the total number of people with income over \(\$50{,}000\) is 96, and among those, 35 are in the 31–45 age group.
\( P(\text{age } 31\text{–}45 \mid \text{income over } \$50{,}000) = \frac{35}{96} \approx 0.36458 \)
\(\boxed{P(\text{age } 31\text{–}45 \mid \text{income over } \$50{,}000) \approx 0.3646}\)
(c)
For two variables to be independent, knowing the value of one variable should not change the probability of the other — in other words, the marginal probability and the conditional probability must be equal.
From part (a), \(P(\text{age } 31\text{–}45) \approx 0.4300\), and from part (b), \(P(\text{age } 31\text{–}45 \mid \text{income over } \$50{,}000) \approx 0.3646\).
Since these two probabilities are not equal (\(0.4300 \neq 0.3646\)), knowing a person’s income category does change the probability of being in the 31–45 age group.
Therefore, annual income and age category are not independent for those in this sample.