
AP Statistics 3.6 p-Values- Exam Style Questions - FRQs - New Syllabus
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(3.6\) — \(p\)-Values (Entire Question)
• Topic \(3.7\) — Carrying Out a Test for a Population Proportion (Entire Question)
▶️ Answer/Explanation
Step 1: State the Hypotheses and Define the Parameter
Let \(p\) represent the true proportion of all students at Karen’s high school who use the application to help them with their homework at least once per week.
\(H_0: p = 0.22\)
\(H_a: p > 0.22\)
Step 2: Identify the Procedure and Check Conditions
The appropriate procedure is a one-sample \(z\)-test for a population proportion.
• Randomness: Karen selected a simple random sample of 130 students from her high school.
• Independence (10% Rule): The sample size of \(n = 130\) is less than 10% of the total high school population, which is stated to be greater than 2,000 students (\(130 \le 0.10 \times 2,000 = 200\)).
• Large Counts Condition: Assuming \(H_0\) is true, the expected number of successes is \(n p_0 = 130 \times 0.22 = 28.6\) and the expected number of failures is \(n(1 – p_0) = 130 \times (1 – 0.22) = 101.4\). Since both values are at least 10 (\(28.6 \ge 10\) and \(101.4 \ge 10\)), a normal distribution can be used to model the sampling distribution of the sample proportion.
Step 3: Calculate the Test Statistic and \(p\)-value
The sample proportion is \(\hat{p} = \dfrac{38}{130} \approx 0.2923\).
The standard error of the sampling distribution is \(\sigma_{\hat{p}} = \sqrt{\dfrac{p_0(1 – p_0)}{n}} = \sqrt{\dfrac{0.22 \times 0.78}{130}} = \sqrt{\dfrac{0.1716}{130}} \approx 0.0363\).
The test statistic is \(z = \dfrac{\hat{p} – p_0}{\sigma_{\hat{p}}} = \dfrac{0.2923 – 0.22}{0.0363} \approx 1.99\).
The \(p\)-value for this one-tailed right test is \(P(Z > 1.99) = 1 – 0.9767 = 0.0233\).
Step 4: Formulate the Conclusion
• Because the computed \(p\)-value (\(0.0233\)) is less than the significance level \(\alpha = 0.05\), we reject the null hypothesis \(H_0\).
• There is convincing statistical evidence to support Karen’s belief that the proportion of all students at her high school who use the app to help them with their homework at least once per week is greater than the national proportion of 0.22.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(3.6\) — \(p\)-Values (Part \( \mathrm{a} \))
• Topic \(3.7\) — Carrying Out a Test for a Population Proportion (Part \( \mathrm{a} \))
• Topic \(3.11\) — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Proportions (Part \( \mathrm{b} \))
▶️ Answer/Explanation
(a)
Let \(p\) be the true proportion of customers who place an order. We test \(H_0: p = 0.40\) against \(H_a: p > 0.40\).
Conditions are met: it’s a random sample, the \(10\%\) rule is satisfied (assume \(\ge 900\) customers), and expected counts \((36, 54)\) are both \(\ge 10\).
The sample proportion is \(\hat{p} = \frac{38}{90} \approx 0.422\), giving a test statistic \(z = \frac{0.422 – 0.40}{\sqrt{0.4(0.6)/90}} \approx 0.430\) and a \(p\)-value of \(0.333\).
Since \(0.333 > 0.05\), we fail to reject \(H_0\); there is not convincing evidence the manager’s belief is correct.
(b)
Because we failed to reject the null hypothesis, a Type II error could have been made.
In context, this means the manager incorrectly thinks the coupon won’t bring in more than \(40\%\) of customers, deciding not to use it and ultimately missing out on a promotion that would have increased sales.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(2.7\) — Independent Events and Unions of Events (Parts \( \mathrm{a} \), \( \mathrm{b} \))
• Topic \(3.6\) — \(p\)-Values (Part \( \mathrm{c} \))
▶️ Answer/Explanation
(a)
Since failures are independent and the failure rate is \(p = 0.15\), the probability that a single super igniter successfully launches a rocket is:
\(P(\text{success}) = 1 – 0.15 = 0.85\)
For the first 30 super igniters to all successfully launch, each of the 30 independent trials must be a success:
\(P(\text{first 30 all succeed}) = (0.85)^{30}\)
\(P(\text{first 30 all succeed}) = (0.85)^{30} \approx 0.0076\)
\(\boxed{P \approx 0.0076}\)
(b)
We are told the first 30 igniters all succeeded. We want the probability that the first failure occurs on either the 31st or the 32nd igniter tested.
For the first failure to occur on the 31st igniter, the 31st must fail. Since failures are independent and we are conditioning on the 30 prior successes:
\(P(\text{failure on 31st}) = 0.15\)
For the first failure to occur on the 32nd igniter, the 31st must succeed AND the 32nd must fail:
\(P(\text{failure on 32nd}) = (0.85)(0.15) = 0.1275\)
These two events are mutually exclusive, so:
\(P(\text{first failure on 31st or 32nd}) = 0.15 + (0.85)(0.15)\)
\(= 0.15 + 0.1275 = 0.2775\)
\(\boxed{P \approx 0.2775}\)
(c)
Yes, it is reasonable to believe that the failure rate of the super igniters is less than 15 percent.
If the failure rate were truly 15 percent (same as the original igniters), the probability of the first 30 super igniters all successfully launching rockets would be only about \(0.0076\), or less than 1 percent. This is an extremely unlikely outcome under the assumption that the failure rate is 15 percent.
Because observing 30 consecutive successes would be so rare if the failure rate were really 15 percent, getting this result in the test provides strong evidence that the true failure rate of the super igniters is lower than 15 percent. The data are inconsistent with a 15 percent failure rate, so it is indeed reasonable to believe the super igniters have a lower failure rate than the original igniters.
Question
A city council wants to estimate the proportion of adult residents who are able to pass a standard physical fitness test. A random sample of 48 adults was selected, and each person was given the fitness test. Of the 48 adults sampled, 20 were able to pass the test.
Most-appropriate topic codes (AP Statistics):
• Topic 3.5 — Setting Up a Test for a Population Proportion (Part b)
• Topic 3.6 — p-Values (Part b)
• Topic 3.7 — Carrying Out a Test for a Population Proportion (Part b)
• Topic 1.12 — Potential Problems with Sampling (Part c)
▶️ Answer/Explanation
(a)
In the context of the study, a Type II error means failing to reject the null hypothesis that 35 percent of adult residents in the city are able to pass the fitness test when, in reality, the true proportion who can pass is actually less than 35 percent.
The real-world consequence of this error is that the city council would decide not to build or fund the new fitness center, even though the community actually needs it because the general health level is lower than desired.
(b)
Because the \(p\)-value of \(0.97\) is much larger than standard significance levels like \(\alpha = 0.05\), the council should fail to reject the null hypothesis.
There is not enough convincing evidence to conclude that the true proportion of adult residents in the city who can pass the test is less than 35 percent.
In fact, the observed sample proportion is:
\(\hat{p} = \dfrac{20}{48} \approx 0.417\)
Since \(0.417\) is actually higher than the baseline value of \(0.35\), it shifts in the opposite direction of what the alternative hypothesis was trying to establish.
(c)
Recruiting volunteers from a local running club creates a non-random, heavily biased sample because runners are typically in much better physical condition than the general public.
Consequently, the sample proportion of success \(\hat{p} = 0.417\) is almost certainly an overestimation of the true proportion \(p\) for all city residents.
This makes any resulting inference invalid, as it hides the true lack of physical fitness among the broader city population and could mistakenly convince the council that a new fitness center is unnecessary.
Question
\(H_a\): The treatment that uses CC alone produces a higher survival rate.
Most-appropriate topic codes (AP Statistics):
• Topic \(3.7\) — Carrying Out a Test for a Population Proportion (Part \(\mathrm{b}\))
• Topic \(3.8\) — Potential Errors When Performing Tests (Part \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
The \(p\)-value of \(0.0761\) is the probability of observing a difference between the two sample survival proportions
\( \hat{p}_{\text{CC}} – \hat{p}_{\text{CC+MMR}} \)
as large as or larger than the one actually observed in this study (\(\frac{35}{240} – \frac{29}{278}\)), assuming that the survival rates for the two treatments are truly equal in the population.
In plain terms: if CC alone and CC + MMR actually produce the same survival rate, there is still about a \(7.61\%\) chance of seeing the CC-alone group outperform the CC + MMR group by as much as (or more than) it did in this study just by random chance alone.
(b)
Compare the \(p\)-value to the significance level:
\( p\text{-value} = 0.0761 > \alpha = 0.05 \)
Because the \(p\)-value exceeds \(\alpha\), we fail to reject \(H_0\).
There is not sufficient evidence at the \(\alpha = 0.05\) significance level to conclude that the treatment using CC alone produces a higher survival rate than CC plus standard MMR for heart attack patients.
Note that since the 518 cases were randomly assigned to the two treatments, this is a properly designed experiment — so a significant result would have allowed a causal conclusion. However, since we fail to reject \(H_0\), we simply cannot make that claim here.
(c)
Because we failed to reject \(H_0\) in part (b), the only error that could have occurred is a Type II error — failing to reject a null hypothesis that is actually false.
In this context, a Type II error would mean that CC alone truly does produce a higher survival rate than CC + MMR, but the study did not provide enough evidence to detect it.
A potential consequence of this error is that the medical community would continue recommending CC plus MMR as the standard treatment for heart attack patients, even though CC alone would actually save more lives. Heart attack patients would receive a less effective treatment, leading to preventable deaths that would not have occurred had CC alone been adopted as the standard practice.
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(4.5\) — Carrying Out a Test for a Population Mean or Population Mean Difference (Part \(\mathrm{a}\): test statistic, \(p\)-value, and conclusion)
• Topic \(2.3\) — Estimating Probabilities Using Simulation (Part \(\mathrm{b}\): simulation-based estimation of a \(p\)-value)
• Topic \(3.6\) — p-Values (Part \(\mathrm{b}\): interpreting simulated \(p\)-value evidence)
▶️ Answer/Explanation
(a)
Let \(\mu\) = the true mean number of fluid ounces dispensed into all juice bottles filled by the machine in the past hour.
Step 1 — Hypotheses:
\(H_0: \mu = 12.1\)
\(H_a: \mu \neq 12.1\)
Step 2 — Test: One-sample \(t\)-test for a mean (conditions are given as met; population standard deviation is unknown).
\(t = \frac{\bar{x} – \mu_0}{s/\sqrt{n}}\)
Step 3 — Mechanics:
Given: \(\bar{x} = 12.05\), \(s = 0.085\), \(n = 4\), \(\mu_0 = 12.1\)
\(t = \frac{12.05 – 12.1}{0.085/\sqrt{4}} = \frac{-0.05}{0.0425} \approx -1.176\)
Degrees of freedom: \(df = n – 1 = 3\)
Two-sided \(p\)-value:
\(p\text{-value} = 2 \cdot P(T_3 < -1.176) \approx 0.324\)
Step 4 — Conclusion:
Since the \(p\)-value of \(0.324\) is much larger than any reasonable significance level (such as \(\alpha = 0.05\)), we fail to reject \(H_0\).
There is not sufficient evidence to conclude that the mean amount of juice being dispensed is different from \(12.1\) fluid ounces. The machine does not need to be shut down on the basis of the mean.
(b)
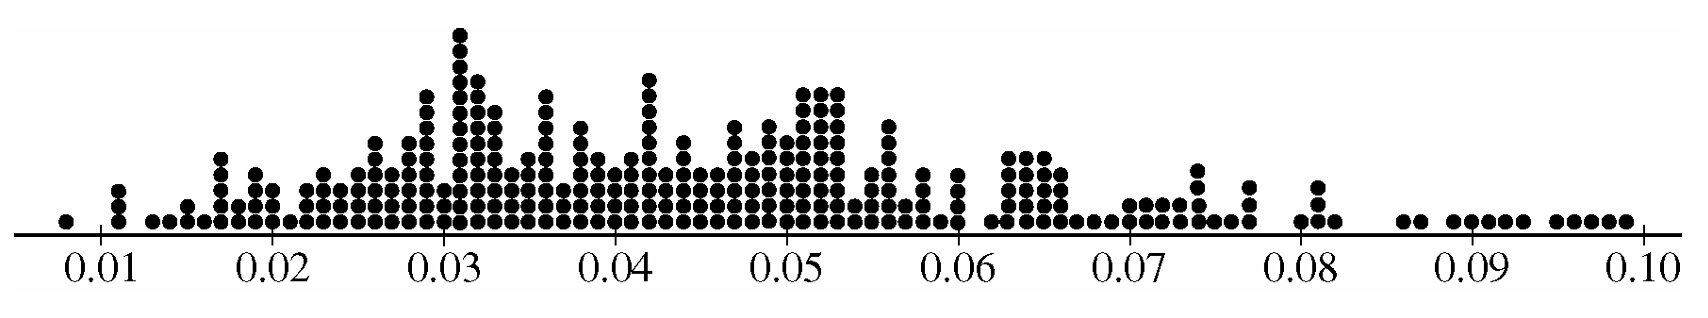
In the simulation, 300 samples of size 4 were drawn from a normal population with \(\sigma = 0.05\). The sample standard deviation of \(s = 0.085\) from our actual data falls well out in the right tail of the dotplot.
Counting the dots at or beyond \(0.085\) in the dotplot, only about 12 out of 300 simulated values are as large or larger than \(0.085\).
This gives an estimated (simulated) \(p\)-value of:
\(\hat{p}\text{-value} = \frac{12}{300} = 0.04\)
Since this simulated \(p\)-value of \(0.04\) is less than \(\alpha = 0.05\), the sample does provide convincing evidence that the true standard deviation of the juice dispensed exceeds \(0.05\) fluid ounce. The machine should be shut down for recalibration.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.12 — Setting Up a Test for the Difference Between Two Population Proportions (Part \(\mathrm{b}\))
• Topic 3.13 — Carrying Out a Test for the Difference Between Two Population Proportions (Part \(\mathrm{c}\))
• Topic 3.6 — p-Values (Part \(\mathrm{d}\))
• Topic 3.13 — Carrying Out a Test for the Difference Between Two Population Proportions (Part \(\mathrm{d}\))
▶️ Answer/Explanation
(a)
This study is classified as an experiment, not an observational study.
The key reason is that the researchers actively imposed treatments on the subjects — they randomly assigned drivers to one of two conditions: driving while using a cell phone, or driving while talking to a passenger.
In an observational study, researchers simply observe subjects without intervening; here, the environment was deliberately controlled and manipulated, which is the defining feature of an experiment.
\(\boxed{\text{Experiment — treatments (cell phone vs. passenger) were actively imposed on randomly assigned subjects.}}\)
(b)
Let \(p_{\text{cell}}\) = the population proportion of drivers who miss the exit while talking on a cell phone.
Let \(p_{\text{pass}}\) = the population proportion of drivers who miss the exit while talking to a passenger.
\(H_0: p_{\text{cell}} = p_{\text{pass}}\) (no difference in the proportion of drivers who miss the exit between the two groups)
\(H_a: p_{\text{cell}} > p_{\text{pass}}\) (a greater proportion of cell phone users miss the exit compared to passenger talkers)
\(\boxed{H_0: p_{\text{cell}} = p_{\text{pass}}, \quad H_a: p_{\text{cell}} > p_{\text{pass}}}\)
(c)
The two conditions required for a two-sample \(z\)-test for proportions are:
Condition 1 — Independent random samples or random assignment: The problem states that the 48 participants were randomly assigned to the two groups, so this condition is met.
Condition 2 — Large sample sizes (each of \(n_1\hat{p}_1\), \(n_1(1-\hat{p}_1)\), \(n_2\hat{p}_2\), \(n_2(1-\hat{p}_2)\) must be \(\geq 10\)):
For the cell phone group: \(n_1\hat{p}_1 = 24\cdot\dfrac{7}{24} = 7 < 10\)
For the passenger group: \(n_2\hat{p}_2 = 24\cdot\dfrac{2}{24} = 2 < 10\)
Both groups fail the large sample condition, so this condition is not met. A two-sample \(z\)-test is therefore not appropriate for this situation.
\(\boxed{\text{Condition 1 met (random assignment); Condition 2 NOT met } (n\hat{p} < 10 \text{ for both groups).}}\)
(d)
In everyday language, the \(p\)-value of \(0.0683\) means: assuming that cell phone use and talking to a passenger are equally distracting (i.e., \(H_0\) is true), there is about a \(6.83\%\) chance of observing a difference in missed-exit proportions as large as or larger than what was seen in this study just by random chance alone.
Since the \(p\)-value of \(0.0683\) is greater than \(\alpha = 0.05\), we fail to reject \(H_0\). We do not have statistically significant evidence at the 5% level to conclude that drivers using a cell phone are more distracted (as measured by missing the freeway exit) than drivers talking to a passenger.
\(\boxed{p\text{-value} = 0.0683 > 0.05 \Rightarrow \text{Fail to reject } H_0; \text{ insufficient evidence that cell phone use causes more distraction.}}\)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.5 — Selecting an Experimental Design (Randomized Block Design) (Part \(\mathrm{a}\))
• Topic 3.6 — Inference and Experiments (Random Assignment) (Part \(\mathrm{b}\))
▶️ Answer/Explanation
(a)
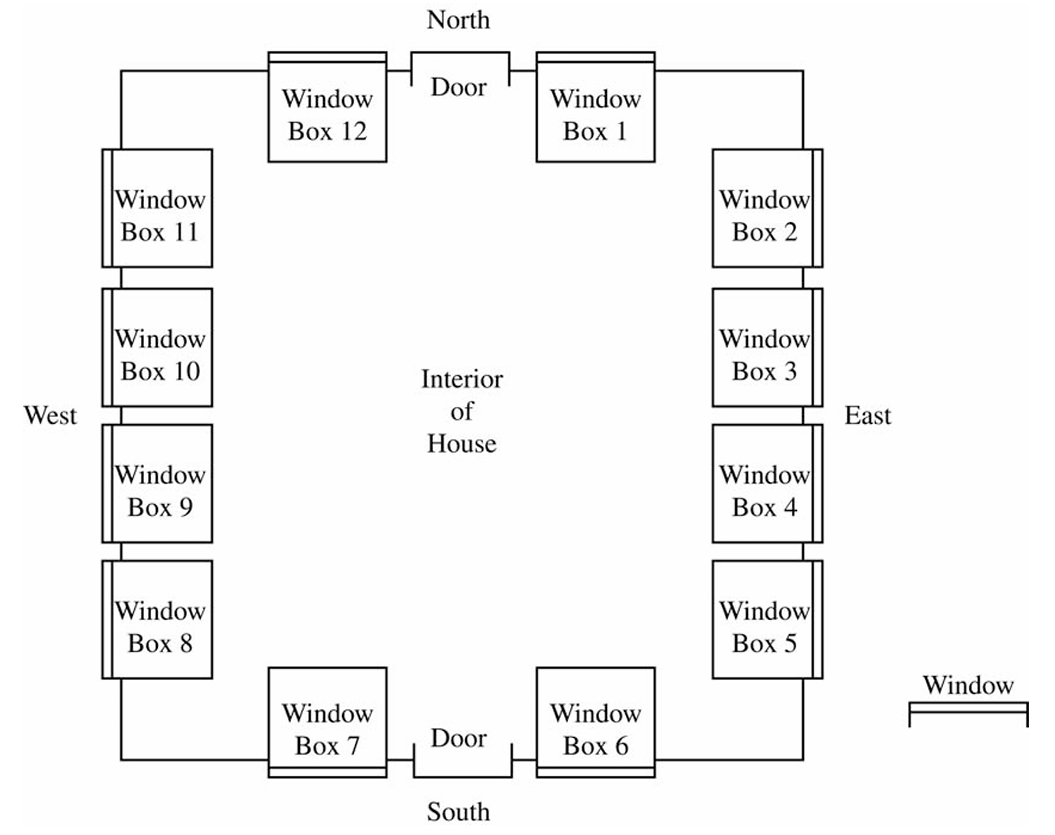
The key variable to control for is sunlight exposure, since windows on different sides of the house receive different amounts of direct sunlight throughout the day, which would directly affect heat gain. Windows on the same side of the house face the same direction and experience approximately the same exposure, so they should be grouped together into the same block.
Since there are two treatments (type A and type B) and six windows of each type, the optimal design creates six blocks of two window boxes each, pairing windows that are on the same side of the house:
Block 1: Window Boxes \(1\) and \(12\) (North wall)
Block 2: Window Boxes \(2\) and \(3\) (East wall)
Block 3: Window Boxes \(4\) and \(5\) (East wall)
Block 4: Window Boxes \(6\) and \(7\) (South wall)
Block 5: Window Boxes \(8\) and \(9\) (West wall)
Block 6: Window Boxes \(10\) and \(11\) (West wall)
This grouping ensures that within each block, both window types experience essentially the same directional sunlight exposure, so any difference in heat gain between the two types can be attributed to the window type itself and not to location.
(b)
Within each block, randomly assign one of the two window boxes to type A and the other to type B. For each block, flip a fair coin — if it lands heads, assign the lower-numbered window box to type A and the higher-numbered to type B; if tails, reverse the assignment. Repeat this process independently for all six blocks. This guarantees that exactly one window of each type appears in every block, and that the assignment is truly random, protecting against any systematic bias in placement.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.2 — Sampling Distributions for Sample Proportions (Part \(\mathrm{b}\))
• Topic 2.10 — The Binomial Distribution (Part \(\mathrm{c}\))
• Topic 3.6 — p-Values (Part \(\mathrm{d}\))
• Topic 3.7 — Carrying Out a Test for a Population Proportion (Part \(\mathrm{e}\))
• Topic 1.13 — Experimental Design (Part \(\mathrm{f}\))
▶️ Answer/Explanation
(a)
Let \(p\) be the population proportion of consumers who prefer Citrus Fresh. The hypotheses are:
\(H_0: p = 0.5\)
\(H_a: p \neq 0.5\)
A two-sided alternative is appropriate because Sunshine Farms wants to detect any difference in preference, not just preference for one particular juice.
(b)
The conditions for a one-proportion \(z\)-test require that both \(np\) and \(n(1-p)\) be at least 5 (or 10). Here:
\(np = 8 \times 0.5 = 4 < 5\)
\(n(1-p) = 8 \times 0.5 = 4 < 5\)
Since both values are less than 5, the large-sample normal approximation is not valid, and using a one-proportion \(z\)-test would not be appropriate for a sample of only \(n = 8\).
(c)
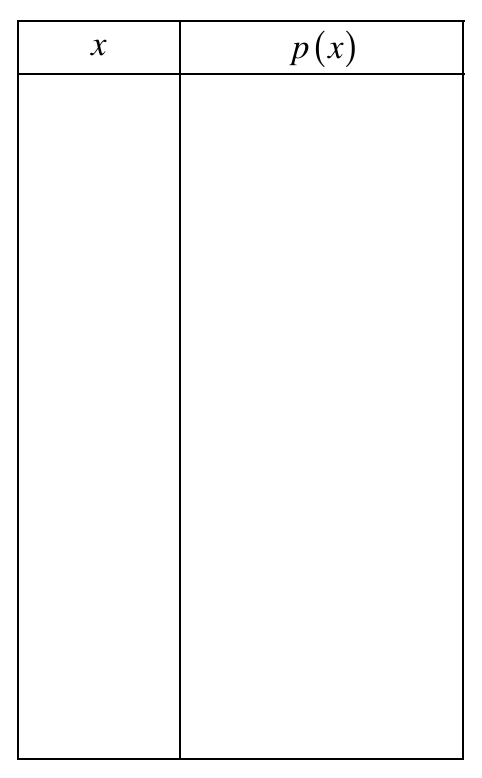
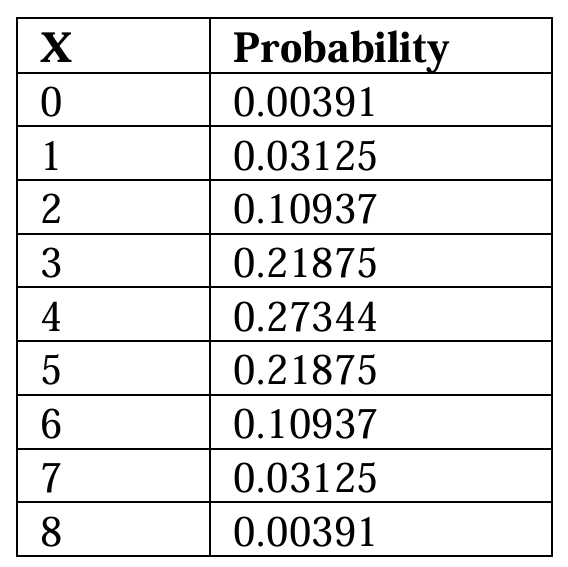
Under \(H_0\), \(X \sim \text{Binomial}(n = 8,\ p = 0.5)\). The probabilities are computed using:
\(P(X = x) = \binom{8}{x}(0.5)^x(0.5)^{8-x} = \binom{8}{x}(0.5)^8\)
(d)
No, it is not possible for the significance level to be exactly 0.05. Because \(X\) is a discrete random variable, the tail probabilities can only take specific values — there is no rejection region that gives a type I error probability of exactly 0.05.
The most extreme rejection region \((X = 0 \text{ or } X = 8)\) gives:
\(\alpha = 2 \times 0.00391 = 0.00782 < 0.05\)
The next possible rejection region \((X \leq 1 \text{ or } X \geq 7)\) gives:
\(\alpha = 2 \times (0.00391 + 0.03125) = 2 \times 0.03516 = 0.07031 > 0.05\)
Since no rejection region produces a type I error probability of exactly 0.05, a significance level of exactly 0.05 is not achievable with this test.
\(\boxed{\alpha = 0.05 \text{ is not achievable — the achievable levels jump from } 0.00782 \text{ to } 0.07031}\)
(e)
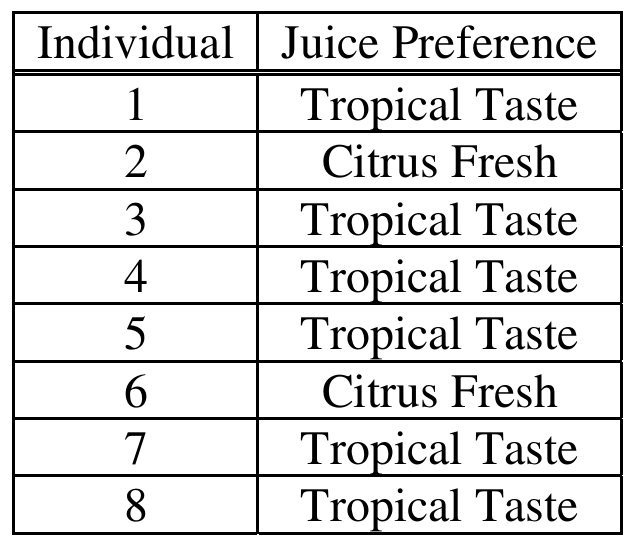
From the data, 2 out of 8 consumers preferred Citrus Fresh, so \(X = 2\).
Since this is a two-sided test, the \(p\)-value is the probability of observing a result at least as extreme as \(X = 2\) in either tail:
\(p\text{-value} = P(X \leq 2) + P(X \geq 6)\)
\(= 2 \times [P(X=0) + P(X=1) + P(X=2)]\)
\(= 2 \times (0.00391 + 0.03125 + 0.10937)\)
\(= 2 \times 0.14453 = 0.28906\)
Since the \(p\)-value of \(0.289\) is much larger than any reasonable significance level (e.g., \(\alpha = 0.05\) or \(\alpha = 0.07031\)), we fail to reject \(H_0\). There is not statistically significant evidence of a consumer preference between Citrus Fresh and Tropical Taste.
\(\boxed{p\text{-value} \approx 0.289 \implies \text{Fail to reject } H_0; \text{ no significant consumer preference detected}}\)
(f)
The most important recommendation is to increase the number of consumers in the study. With only \(n = 8\) consumers, the test has very low power — even a large true difference in preference (like 75% vs. 25%) may not produce a statistically significant result. Increasing the sample size would reduce the standard error of the estimated proportion \(\hat{p}\), making it easier to detect a real difference, and would allow the use of the large-sample one-proportion \(z\)-test since \(np \geq 5\) and \(n(1-p) \geq 5\) would be satisfied. For example, with \(n = 80\) and \(X = 20\) (same sample proportion of 0.25), the \(z\)-statistic would be approximately:
\(z = \frac{0.25 – 0.5}{\sqrt{\frac{0.5(0.5)}{80}}} \approx -4.47\)
which gives a \(p\)-value near zero, allowing a clear conclusion to be reached.
\(\boxed{\text{Recommendation: Increase sample size to increase power and enable use of the } z\text{-test}}\)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 3.7 — Carrying Out a Test for a Population Proportion (conditions, mechanics, conclusion)
• Topic 3.6 — p-Values (interpretation of statistical evidence)
▶️ Answer/Explanation
Step 1: Hypotheses
Let \(p\) = the true proportion of boxes of this cereal that contain a voucher.
\( H_0: p=0.2 \)
\( H_a: p<0.2 \)
Step 2: Test and conditions
This is a one-sample \(z\)-test for a proportion:
\( z=\dfrac{\hat{p}-p_0}{\sqrt{\dfrac{p_0(1-p_0)}{n}}} \)
Checking conditions:
\( np_0=65(0.2)=13\ge 10 \)
\( n(1-p_0)=65(0.8)=52\ge 10 \)
It’s reasonable that there are at least \(650\) boxes of this cereal in total, so the \(10\%\) condition is met, and the stem tells us the sample is random, so the observations are independent.
Step 3: Mechanics
The sample proportion is
\( \hat{p}=\dfrac{11}{65}\approx 0.169 \)
The test statistic is
\( z=\dfrac{0.169-0.2}{\sqrt{\dfrac{0.2(1-0.2)}{65}}} \)
\( z\approx -0.62 \)
The corresponding p-value is
\( P(Z<-0.62)\approx 0.2676 \)
\( \boxed{z\approx -0.62,\quad p\text{-value}\approx 0.2676} \)
Step 4: Conclusion
A p-value of \(0.2676\) is large — much bigger than any typical significance level like \(0.05\). This means a sample proportion as low as \(0.169\) wouldn’t be at all surprising if the true proportion really were \(0.2\), so there isn’t enough evidence to reject the company’s claim.
\( \boxed{\text{Since the p-value (0.2676) is large, we fail to reject } H_0\text{ — no significant evidence that } p<0.2} \)