
AP Statistics 4.7 Constructing a Confidence Interval for the Difference Between Two Population Means- Exam Style Questions - FRQs - New Syllabus
Question
\(H_a : \mu > 122\)
Most-appropriate topic codes (AP Statistics):
• Topic \(4.5\) — Carrying Out a Test for a Population Mean (Part \( \mathrm{b} \))
• Topic \(4.7\) — Constructing a Confidence Interval for the Difference Between Two Population Means (Parts \( \mathrm{c} \), \( \mathrm{d} \), \( \mathrm{e} \))
▶️ Answer/Explanation
(a)
A Type II error occurs when the alternative hypothesis is actually true, but we fail to reject the null hypothesis.
In this context, a Type II error would occur if the true mean systolic blood pressure of all employees is greater than 122 mmHg, but the hypothesis test does not detect this — that is, the null hypothesis (\(H_0 : \mu = 122\)) is not rejected.
In plain terms: the employees really do have higher-than-national-average blood pressure, but the test fails to conclude so.
(b)
Since this is a one-sided (right-tailed) test with known \(\sigma\), we reject \(H_0\) when the test statistic exceeds the critical value \(z^* = 1.645\) at \(\alpha = 0.05\).
The test statistic is \(z = \dfrac{\bar{x} – \mu_0}{\sigma / \sqrt{n}} = \dfrac{\bar{x} – 122}{15/\sqrt{100}} = \dfrac{\bar{x} – 122}{1.5}\).
Setting \(\dfrac{\bar{x} – 122}{1.5} > 1.645\) and solving:
\(\bar{x} – 122 > 1.645 \times 1.5 = 2.4675\)
\(\boxed{\bar{x} > 124.4675 \text{ mmHg}}\)
Any sample mean greater than approximately 124.47 mmHg provides sufficient evidence to reject \(H_0\) at the \(\alpha = 0.05\) level.
(c)
Now the true population mean is \(\mu = 125\) mmHg (with \(\sigma = 15\), \(n = 100\)), so the sampling distribution of \(\bar{x}\) is approximately normal with mean 125 and standard deviation \(\dfrac{15}{\sqrt{100}} = 1.5\).
We want the probability that \(\bar{x}\) falls in the rejection region found in part (b):
\(P(\bar{x} > 124.4675) = P\!\left(z > \dfrac{124.4675 – 125}{1.5}\right) = P(z > -0.355)\
Folk \boxed{P(z > -0.355) \approx 0.64}\)
There is approximately a 64% probability that the null hypothesis will be rejected when the true mean is 125 mmHg.
(d)
The probability found in part (c) — the probability of correctly rejecting a false null hypothesis — is called the power of the test.
\(\boxed{\text{Power of the test} \approx 0.64}\)
(e)
The probability of rejecting \(H_0\) would be greater than 0.64 if the sample size is larger than 100.
A larger sample size \(n\) reduces the standard error of \(\bar{x}\): \(\sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}}\), so the sampling distribution becomes narrower.
This means the critical value \(\bar{x}^* = \mu_0 + z^* \cdot \dfrac{\sigma}{\sqrt{n}}\) would be smaller (closer to 122), lowering the threshold needed to reject \(H_0\).
With a lower rejection threshold, it becomes more likely that \(\bar{x}\) exceeds that threshold when the true mean is 125 mmHg — so the power of the test increases.
\(\boxed{\text{Probability of rejecting } H_0 \text{ would be greater than 0.64.}}\)
Question
Most-appropriate topic codes (AP Statistics):
• Topic \(4.8\) — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Means (Part \(\mathrm{b}\))
▶️ Answer/Explanation
(a)
Step 1 — Identify the procedure and check conditions
Let \(\mu_N\) = true mean response time (in minutes) for calls to the northern fire station, and \(\mu_S\) = true mean response time for calls to the southern fire station.
We will construct a two-sample \(t\)-interval for \(\mu_N – \mu_S\):
\( (\bar{x}_N – \bar{x}_S) \pm t^* \sqrt{\dfrac{s_N^2}{n_N} + \dfrac{s_S^2}{n_S}} \)
Conditions:
1. Independent random samples: The problem states that both samples were randomly selected, and the northern and southern calls are independent of each other.
2. Large samples: Both sample sizes are \(n_N = n_S = 50 > 30\), so by the Central Limit Theorem the sampling distribution of \(\bar{x}_N – \bar{x}_S\) is approximately normal, even without knowing the shape of the population distributions.
Step 2 — Mechanics
The known values are:
\( \bar{x}_N = 4.3,\quad s_N = 3.7,\quad n_N = 50 \)
\( \bar{x}_S = 5.3,\quad s_S = 3.2,\quad n_S = 50 \)
Point estimate of the difference:
\( \bar{x}_N – \bar{x}_S = 4.3 – 5.3 = -1.0 \text{ minutes} \)
Standard error of the difference:
\( SE = \sqrt{\dfrac{s_N^2}{n_N} + \dfrac{s_S^2}{n_S}} = \sqrt{\dfrac{3.7^2}{50} + \dfrac{3.2^2}{50}} = \sqrt{\dfrac{13.69}{50} + \dfrac{10.24}{50}} = \sqrt{0.2738 + 0.2048} = \sqrt{0.4786} \approx 0.6918 \)
Using conservative degrees of freedom \(df = 49\) (smaller of \(n_N – 1\) and \(n_S – 1\)), the critical value from the \(t\)-table is:
\( t^* \approx 2.010 \quad (df = 49,\ 95\%\ \text{confidence}) \)
The 95% confidence interval is:
\( -1.0 \pm 2.010 \times 0.6918 = -1.0 \pm 1.390 \)
\( \boxed{(-2.39,\ 0.39) \text{ minutes}} \)
Step 3 — Interpretation
Based on these samples, we are 95% confident that the true difference in mean response times (northern minus southern) is between \(-2.39\) minutes and \(0.39\) minutes.
In other words, the northern fire station’s mean response time could be anywhere from about 2.39 minutes faster to about 0.39 minutes slower than the southern fire station’s mean response time.
(b)
The confidence interval \((-2.39,\ 0.39)\) does not support the council member’s belief that the two fire stations have different mean response times.
The value \(0\) is contained within the interval, which means a true difference of \(\mu_N – \mu_S = 0\) (i.e., equal mean response times) is a plausible value based on the data. Because zero is a plausible value for the difference, we cannot conclude that a difference in mean response times actually exists.
It would be statistically incorrect to say the council member is definitely wrong — we simply don’t have sufficient evidence from this data to confirm a difference exists.
Question
Most-appropriate topic codes (AP Statistics):
• Topic 1.9 — Comparisons of the Distributions for One Quantitative Variable (Part \(\mathrm{b}\))
• Topic 4.7 — Constructing a Confidence Interval for the Difference Between Two Population Means (Part \(\mathrm{c}\))
• Topic 4.8 — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Means (Part \(\mathrm{c}\))
▶️ Answer/Explanation
(a)
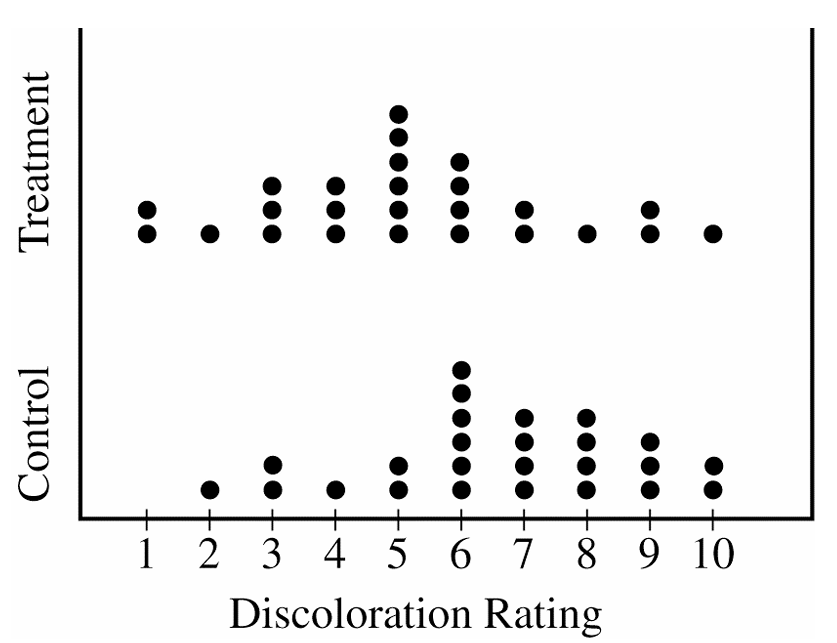
The standard deviation \(s = 2.141\) tells us roughly how far a typical discoloration rating in the control group falls from the group’s mean rating.
In other words, on average, a single strawberry’s discoloration rating in the control group deviates from the mean discoloration rating by about \(2.141\) points.
A larger standard deviation would indicate that the individual ratings are more spread out from the mean, while a smaller value would indicate the ratings are clustered more tightly around the mean.
\(\boxed{s = 2.141 \text{ is the typical distance of each discoloration rating from the mean in the control group.}}\)
(b)
The preservative does appear to have been effective in lowering the amount of discoloration in strawberries.
Looking at the dotplots, the treatment group’s distribution is clearly centered at a lower value than the control group’s distribution — the treatment group’s center is around 5, while the control group’s center is around 7.
Additionally, nearly all the summary statistics (minimum, \(Q_1\), median, and \(Q_3\)) are lower for the treatment group than for the control group, which consistently supports the conclusion that the preservative reduced discoloration.
\(\boxed{\text{The preservative appears effective: treatment ratings are consistently lower than control ratings.}}\)
(c)
We are given a 95% confidence interval for \(\mu_{\text{control}} – \mu_{\text{treatment}}\) as \((0.16,\ 2.72)\).
Since the entire interval lies above zero — meaning zero is not contained within \((0.16,\ 2.72)\) — we have convincing evidence that the two population means are not equal.
We are 95% confident that the population mean discoloration rating for untreated strawberries is between \(0.16\) and \(2.72\) units higher than the population mean rating for treated strawberries, indicating the preservative does make a real difference.
\(\boxed{0 \notin (0.16,\ 2.72) \Rightarrow \text{there is a significant difference in population mean discoloration ratings.}}\)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 4.8 — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Means (Part \(\mathrm{b}\))
▶️ Answer/Explanation
(a)
We use a two-sample \(t\)-interval for \(\mu_A – \mu_S\), the difference in mean wait times (Ambulance \(-\) Self).
Conditions:
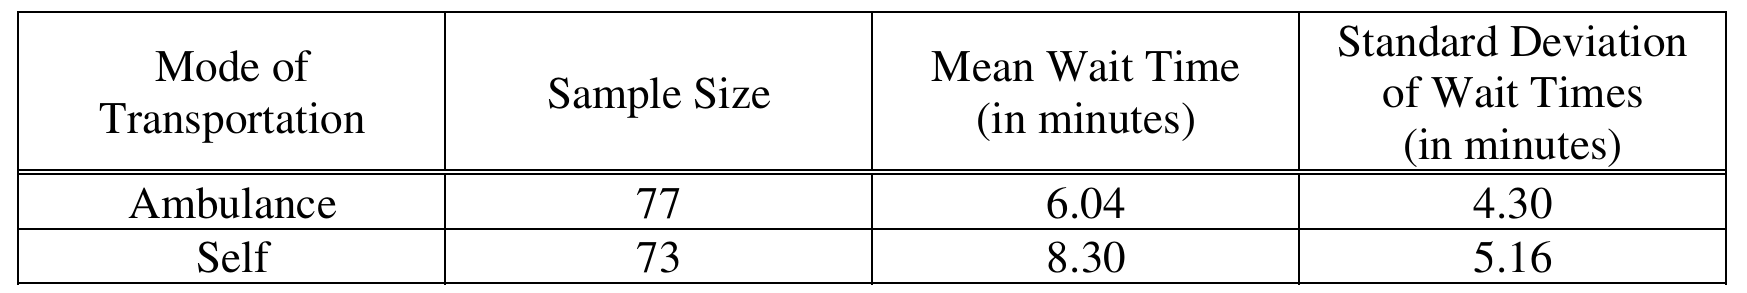
The 150 patients were randomly selected, so it is reasonable to treat the ambulance and self-transport groups as independent random samples. Both sample sizes are large (\(n_A = 77 > 30\) and \(n_S = 73 > 30\)), so by the Central Limit Theorem the sampling distributions of the sample means are approximately normal.
Mechanics:
Using the conservative degrees of freedom \(df = \min(77-1,\, 73-1) = 72\) and \(t^* = 2.6459\) at the 99% level:
\((\bar{x}_A – \bar{x}_S) \pm t^* \sqrt{\frac{s_A^2}{n_A} + \frac{s_S^2}{n_S}}\)
\((6.04 – 8.30) \pm 2.6459\sqrt{\frac{4.30^2}{77} + \frac{5.16^2}{73}}\)
\(-2.26 \pm 2.6459\sqrt{\frac{18.49}{77} + \frac{26.63}{73}}\)
\(-2.26 \pm 2.6459\sqrt{0.2401 + 0.3648}\)
\(-2.26 \pm 2.6459 \times 0.7778\)
\(-2.26 \pm 2.0577\)
\(\boxed{(-4.318,\ -0.202)}\)
Interpretation: Based on this sample, we are 99% confident that the true difference in population mean wait times (Ambulance \(-\) Self) is between \(-4.318\) minutes and \(-0.202\) minutes. That is, ambulance-transported patients wait, on average, somewhere between about 0.2 and 4.3 minutes less than self-transported patients.
(b)
Yes, the difference in mean wait times is statistically significant at the \(\alpha = 0.01\) level.
Since the value \(0\) is not contained in the 99% confidence interval \((-4.318,\ -0.202)\), we can reject \(H_0: \mu_A – \mu_S = 0\) in favor of \(H_a: \mu_A – \mu_S \neq 0\) at the \(\alpha = 0.01\) significance level.
There is sufficient evidence to conclude that the mean wait time for ambulance-transported patients is significantly different from (specifically, shorter than) the mean wait time for self-transported patients.
\(\boxed{0 \notin (-4.318,\ -0.202) \implies \text{Reject } H_0 \text{ at } \alpha = 0.01}\)
Question
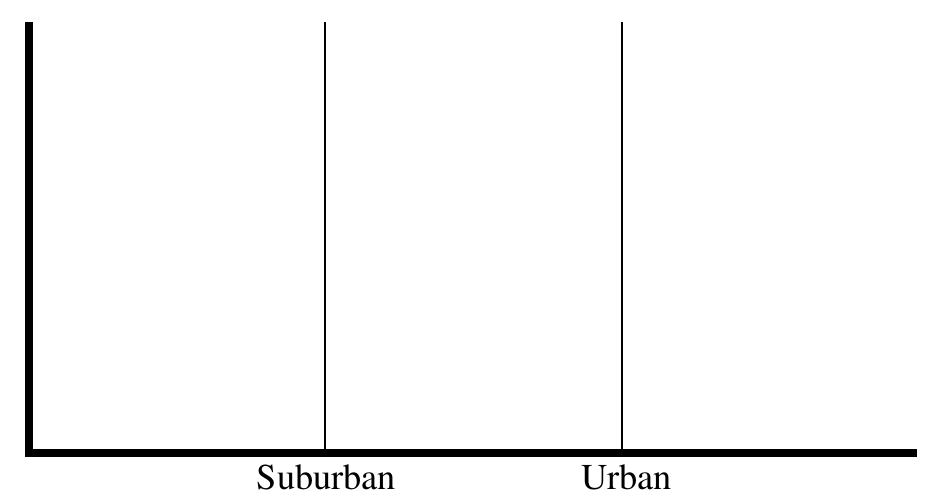
• Connect these two points with a line segment.
• Plot the two means (suburban and urban) for the children who played outside at the two types of day-care centers.
• Connect these two points with a second line segment.
Most-appropriate topic codes (AP Statistics):
• Topic 4.8 — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Means (Part a, Part c)
• Topic 5.1 — Graphical Representations Between Two Quantitative Variables (Part b)
▶️ Answer/Explanation
(a)
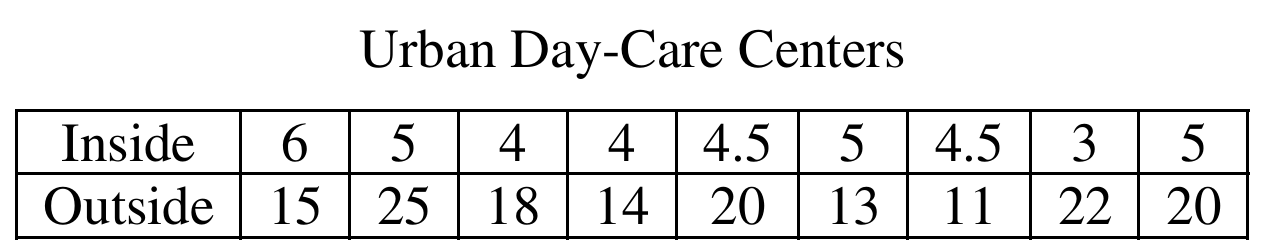
First check conditions for a two-sample \(t\)-interval: the two groups of urban children were assigned at random and independently to play inside or outside, and dotplots of each group’s data show no strong skew or outliers, so it’s reasonable to treat the underlying populations as approximately normal.
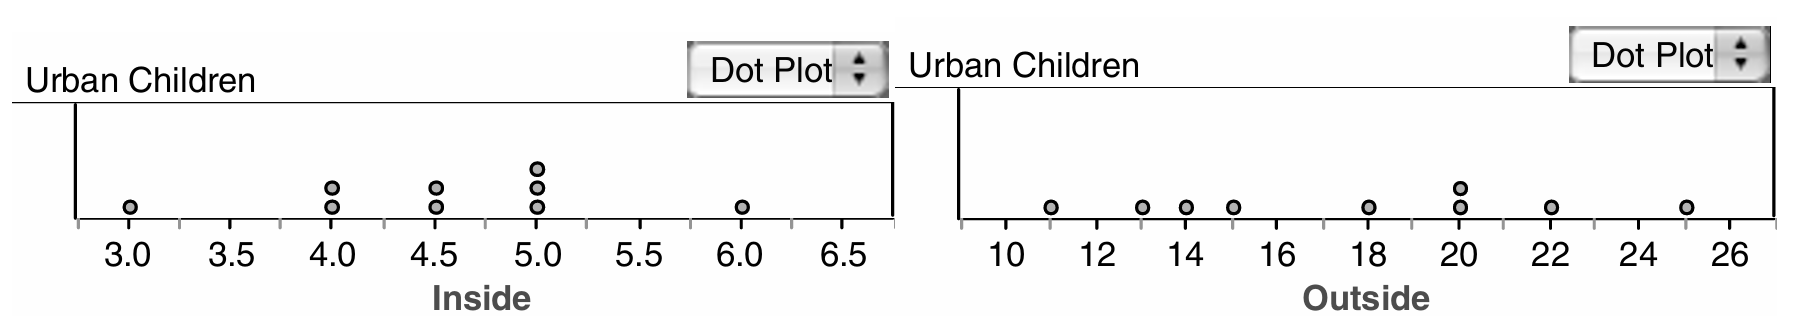
Summary statistics for the urban sample:
\( n_{\text{in}}=9,\quad \bar{x}_{\text{in}}=4.56,\quad s_{\text{in}}=0.846 \)
\( n_{\text{out}}=9,\quad \bar{x}_{\text{out}}=17.56,\quad s_{\text{out}}=4.61 \)
The two-sample \(t\)-confidence interval formula is
\( (\bar{x}_{\text{in}}-\bar{x}_{\text{out}})\pm t^*\sqrt{\dfrac{s_{\text{in}}^2}{n_{\text{in}}}+\dfrac{s_{\text{out}}^2}{n_{\text{out}}}} \)
Using the conservative degrees of freedom \(df=\min(n_{\text{in}}-1,\,n_{\text{out}}-1)=8\), so \(t^*=2.306\):
\( (4.56-17.56)\pm 2.306\sqrt{\dfrac{(0.846)^2}{9}+\dfrac{(4.61)^2}{9}} \)
\( -13.00\pm 2.306(1.564) \)
\( -13.00\pm 3.61 \)
\( \boxed{(-16.60,\ -9.40)\text{ mcg}} \)
Interpretation: we are 95% confident that, for the population of urban day-care children, the mean amount of lead on the dominant hand after an hour of play inside is between 9.40 and 16.60 mcg lower than after an hour of play outside. Since this interval doesn’t contain zero, the difference is meaningful — urban children who play outside pick up noticeably more lead on their hands.
(b)
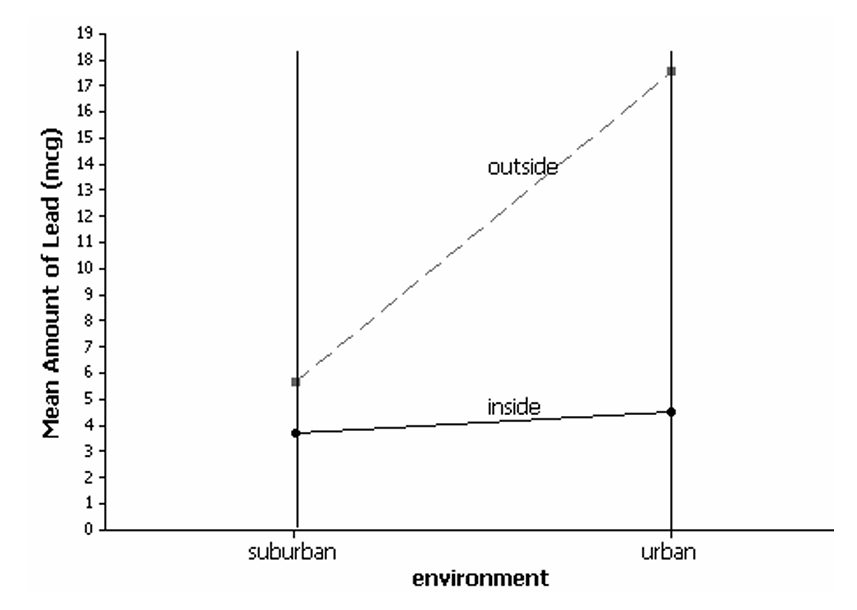
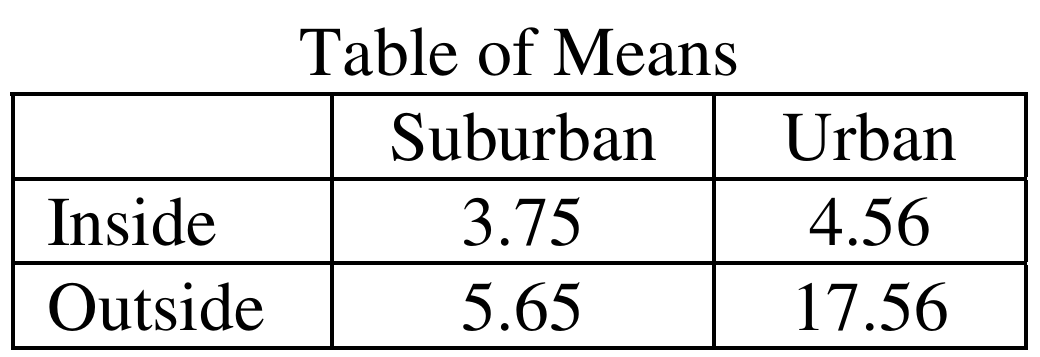
Plot the points \((\text{Suburban},3.75)\) and \((\text{Urban},4.56)\), connect them with a line labeled “inside.” Then plot \((\text{Suburban},5.65)\) and \((\text{Urban},17.56)\), connect them with a line labeled “outside.” The “inside” line should be nearly flat and low on the graph, while the “outside” line should rise sharply from suburban to urban.
\( \boxed{\text{Inside line: nearly flat, low values; Outside line: steep increase from suburban to urban}} \)
(c)
Setting (inside vs. outside): In both suburban and urban environments, children who played outside ended up with more lead on their hands than children who played inside. This is supported by the fact that all four endpoints of the two confidence intervals (inside minus outside) are negative, and the graph shows the “outside” line sitting above the “inside” line everywhere.
Environment (suburban vs. urban): For both inside and outside play, urban children had more lead on their hands on average than suburban children. The graph shows both lines sloping upward from suburban to urban.
Relationship between the two: The effect of going inside versus outside depends heavily on the environment. In the suburban setting, the inside and outside means are fairly close together (3.75 vs. 5.65), but in the urban setting the gap is much larger (4.56 vs. 17.56). In other words, playing outside makes a much bigger difference in lead exposure in the urban environment than in the suburban environment.
\( \boxed{\text{Outside > Inside in both settings; Urban > Suburban in both settings; the inside/outside gap is much larger for urban than suburban}} \)
Question
Most-appropriate topic codes (AP Statistics):
• Topic 4.8 — Justifying a Claim Based on a Confidence Interval for the Difference Between Two Population Means (Part a)
• Topic 4.7 — Constructing a Confidence Interval for the Difference Between Two Population Means (Part b)
▶️ Answer/Explanation
(a)
We use a two-sample \(t\)-interval for the difference in means \((\mu_1 – \mu_2)\), where:
\(\mu_1\) = mean homework time for all sixth-graders at Crest Middle School
\(\mu_2\) = mean homework time for all seventh-graders at Crest Middle School
Assumptions checked: The two samples are independent random samples. The dotplots indicate that it is not unreasonable to assume approximate normality for both groups. So we may proceed.
The general form of the two-sample \(t\)-interval is:
\((\bar{X}_1 – \bar{X}_2) \pm t^* \sqrt{\dfrac{s_1^2}{n_1} + \dfrac{s_2^2}{n_2}}\)
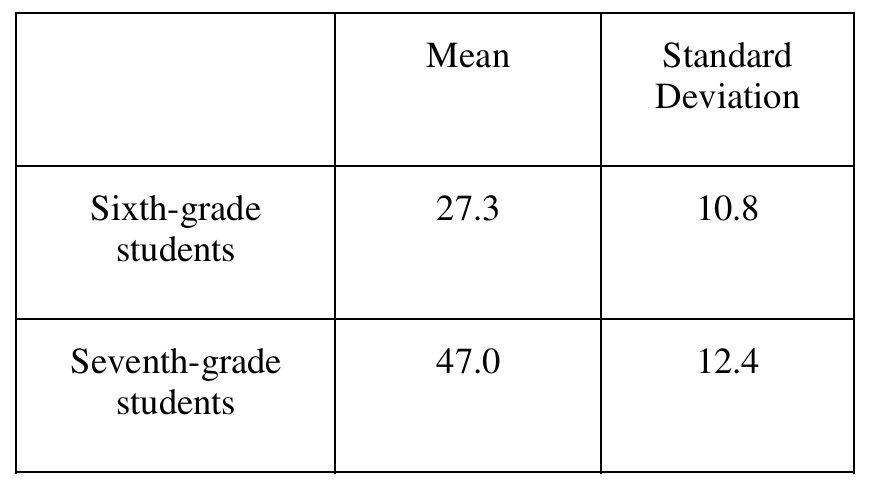
Substituting the values (using sixth-grade as group 1 and seventh-grade as group 2):
\((27.3 – 47.0) \pm t^* \sqrt{\dfrac{10.8^2}{20} + \dfrac{12.4^2}{20}}\)
\(-19.7 \pm t^* \sqrt{\dfrac{116.64}{20} + \dfrac{153.76}{20}}\)
\(-19.7 \pm t^* \sqrt{5.832 + 7.688} = -19.7 \pm t^* \sqrt{13.52} = -19.7 \pm t^*(3.68)\)
Using \(t^* = 2.026\) based on approximately 37.297 degrees of freedom at a 95% confidence level:
\(-19.7 \pm 2.026 \times 3.68 = -19.7 \pm 7.45\)
\(\boxed{(-27.15,\ -12.25)}\)
Interpretation: Based on these samples, we can be 95% confident that the true difference in mean homework times (sixth-graders minus seventh-graders) for all students at Crest Middle School is between \(-27.15\) minutes and \(-12.25\) minutes. That is, seventh-graders spend, on average, between about 12.25 and 27.15 more minutes per night on homework than sixth-graders.
(b)
No, the assistant principal’s suggestion is not a valid procedure, and it would not produce a better confidence interval. Matching students based on their homework time responses — pairing the highest sixth-grader with the highest seventh-grader, and so on — is inappropriate for two key reasons.
First, valid matched-pairs designs require that pairs be formed before data are collected, based on some variable related to the response (such as prior GPA, study habits, or some pre-existing characteristic), not on the response variable itself. Pairing after the fact on the observed response creates an artificial association between the two independent samples.
Second, because the two samples were drawn independently with no natural connection between any sixth-grader and any seventh-grader, forcing them into pairs based on their ranked responses would artificially inflate the correlation between the paired differences. This would produce a confidence interval that is misleadingly narrow and fails to achieve the stated confidence level, giving a false impression of precision.