
IBDP Computer Science A4.3 Machine learning approaches HL Paper 2 - New Syllabus
Question
Genetic algorithms are based on Darwin’s theory of natural selection. The process selects the fittest individuals.
Developments in machine learning and neural networks have led to simulations that are able to beat the leading human players of games. For example, Deep Blue beat Garry Kasparov in chess, and Alpha Go beat Fan Hui in go (a Chinese strategy board game).
The neural network used to defeat Fan Hui used the go board (see Figure 6) as an input device.
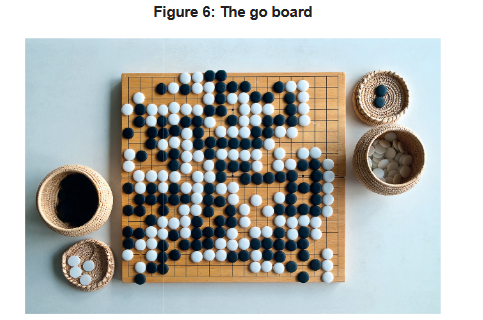
Within the neural network there is a policy layer that selects the next move. There is also a value network that predicts the winner of the game.
Neural networks can be used in a variety of contexts, such as for predicting outcomes of board games like go and chess or for natural language processing.
Most-appropriate topic code
▶️ Answer/Explanation
(a)
For the correct answer, any three valid phases of a genetic algorithm may be identified:
- Establish the initial population.
- Define the fitness function.
- Selection.
- Crossover.
- Mutation.
- Evaluation.
- Replacement.
- Reproduction.
Explanation: A genetic algorithm begins with a population of possible solutions. Individuals are evaluated using a fitness function, and suitable individuals are selected for reproduction. Crossover and mutation introduce variation, after which the resulting population can be evaluated and replaced or reproduced over successive generations.
(b)
For the correct answer, any two of:
- Input layer
- One or more hidden layers
- Output layer
Explanation: The input layer receives the data, hidden layers process the information, and the output layer produces the prediction or classification.
(c)
For the correct answer:
- Teach the neural network the rules for moves that are allowed in the game.
- Train it using typical moves based on previous moves and game positions.
- Allow the neural network to predict moves based on previous moves and the current board position.
- Allow the network to learn from the results of games, including games played against human players of different abilities or against itself.
- Use feedback from the results and the value network to modify the network’s decision-making and judge how successful its predictions have been.
Explanation: The neural network can progressively improve by receiving board positions and learning which moves are associated with successful outcomes. Self-play provides a large number of additional examples from which the network can learn patterns and improve its decisions.
(d)
For the correct answer:
Supervised learning:
- Supervised learning uses labelled data.
- The network is trained using known outcomes associated with given inputs.
- This can make the resulting predictions more predictable because the desired outcomes are already provided during training.
Unsupervised learning:
- Unsupervised learning uses unlabelled data.
- The AI learns by identifying patterns and relationships in the data with minimal human input.
- This can lead to less predictable outcomes because no predefined correct output is supplied.
Conclusion: Unsupervised learning can be more exploratory and potentially discover deeper or unexpected patterns, whereas supervised learning generally produces more predictable results because it learns from labelled examples.
(e)
For the correct answer, suitable developments include:
- Pre-trained language models and transfer learning: models are pre-trained using large datasets and can then be fine-tuned for specific tasks using a smaller labelled dataset.
- Transformer architecture: self-attention mechanisms allow the model to identify relationships between words and model long-range dependencies in text.
- Transformers can process sequences in parallel, allowing faster and more effective training on large datasets.
- Contextual embeddings: words can be represented according to their context, improving semantic understanding and reducing ambiguity.
- Larger and more diverse training datasets: these can reduce bias, improve robustness, and improve understanding of language nuances and idioms.
Explanation: Advances in NLP allow neural networks to consider more of the surrounding context when interpreting language. For example, the meaning of a word can change depending on the surrounding words. Contextual representations and transformer-based architectures therefore allow predictions to be made using richer information than earlier approaches.